Medium companion: AI Security Course, Module 00 — Chapter 4 ↗. This page is the canonical course edition with locally preserved visuals, cross-links, and the assessed analyst exercise.
Trace an LLM request from structured messages to generated output, then place authorization, validation, and forensic evidence at the boundaries that actually enforce security.
This chapter explains how an application turns messages into tokens, how a Transformer produces next-token scores, how decoding turns those scores into text, and where security controls and evidence must exist around the model.
It is written for security engineers, CTI analysts, detection engineers, incident responders, and technical leaders who need to investigate an LLM-enabled application without treating fluent output as proof. The objective is a repeatable request trace: identify each artifact and trust boundary, reproduce behavior under controlled conditions, and distinguish generated text from an authorized or executed action.
Scope and safety: Use only course-owned systems or environments you are authorized to test. The practical uses harmless marker strings and does not require production data, reusable credentials, destructive tool calls, or attempts to extract another user's information. If a provider processes the test remotely, follow its data-handling rules and do not send confidential evidence.
Chapter status: Complete. Originally published on 15 August 2026 and finalized on 31 August 2026, this canonical course version closes the evidence review, preserves the reviewed visuals locally, and includes the assessed analyst exercise. The Medium article remains the original companion publication.
Learning outcomes
After completing this chapter, you should be able to:
- trace one request from application messages to a generated response;
- distinguish tokenizer, vocabulary, chat template, model artifact, context, logits, decoding policy, and application policy;
- explain attention conceptually without treating it as explanation, authorization, or factual verification;
- identify security-relevant truncation, role-boundary, serialization, generation, and logging failures;
- state a prompt-injection or extraction claim with an explicit threat model and evidence level; and
- design a reproducible LLM test record that separates model behavior from application behavior.
Table of contents
- 1. Why the generation mechanism matters to security
- 2. The complete LLM request path
- 3. Tokenization and the model interface
- 4. Chat templates and instruction serialization
- 5. Embeddings and positional information
- 6. Self-attention: learned information flow
- 7. The Transformer block
- 8. Causal language modeling and next-token prediction
- 9. Context windows, truncation, and KV cache
- 10. Decoding and generation controls
- 11. Determinism, reproducibility, and evidence
- 12. Structured output is not authorization
- 13. Prompt injection and instruction conflicts
- 14. Extraction, leakage, and sensitive context
- 15. CTI case study: indirect prompt injection
- 16. Controls, ATLAS mapping, and analyst exercise
- 17. Limitations and scope boundaries
- 18. Key takeaways
- 19. What comes next
- 20. Conclusion
- 21. References
- 22. Follow My Work
1. Why the generation mechanism matters to security
An LLM does not receive a conversation as separate colored chat bubbles. The application serializes messages, retrieved text, tool descriptions, memory, and control markers into a model-specific sequence. A tokenizer converts that sequence into token IDs. The model produces scores for possible next tokens, and a decoding procedure chooses what to append. The process repeats until a stop condition is reached.
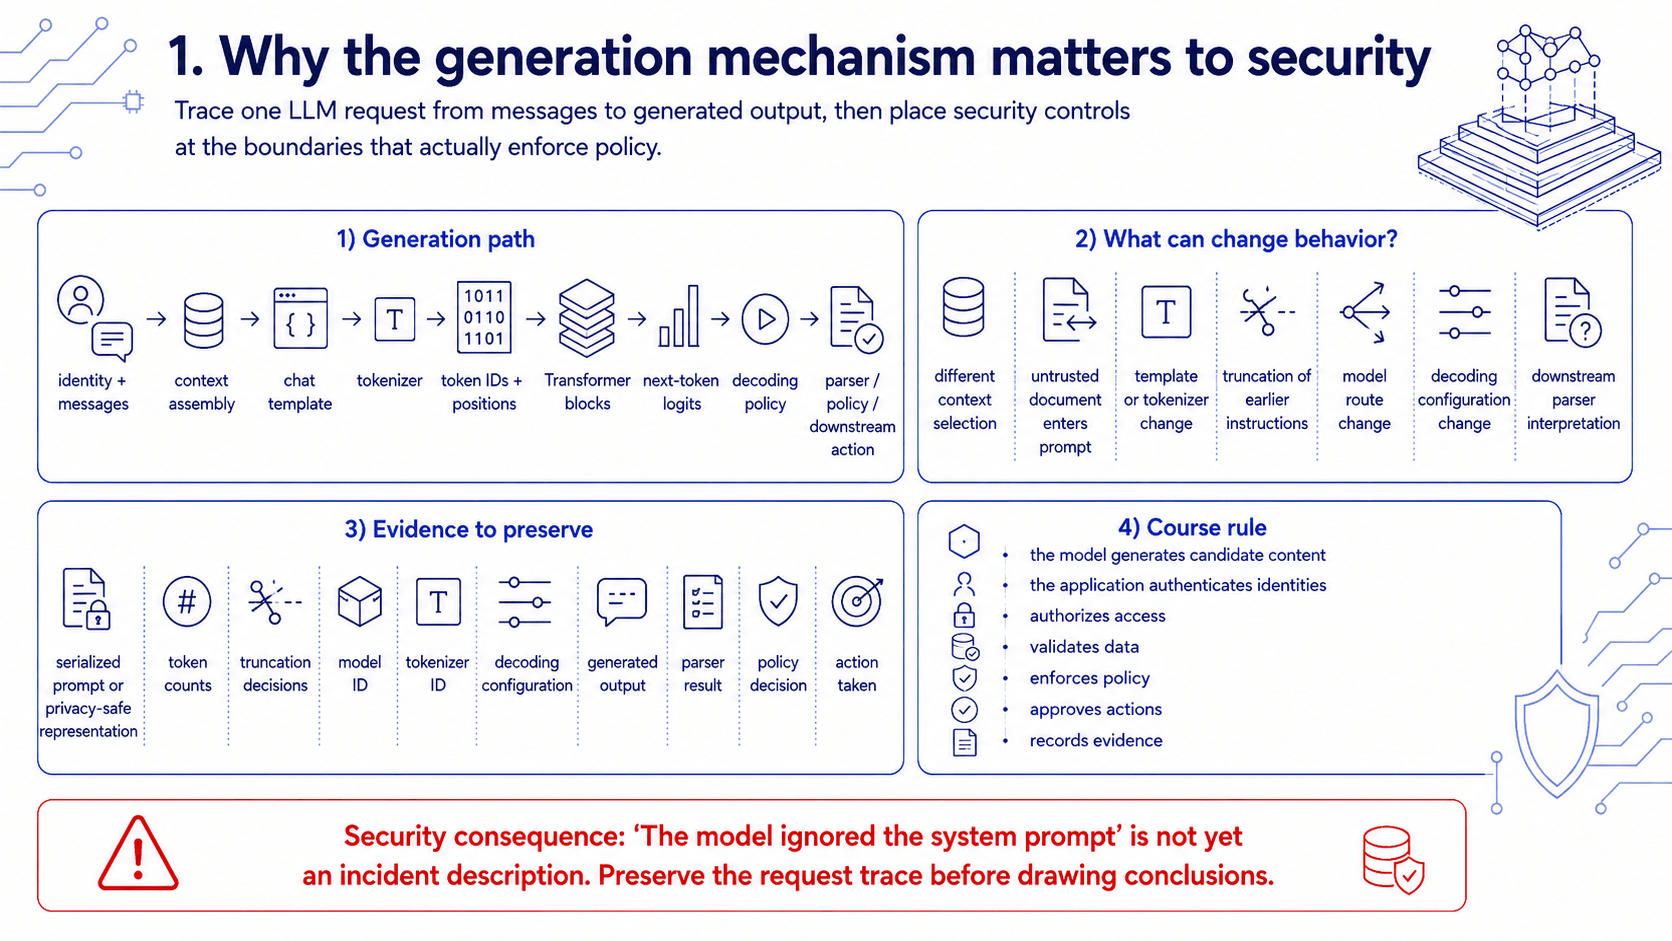
identity + messages + application state
  → authorization and context assembly
  → model-specific chat template
  → tokenizer and special tokens
  → token IDs and positions
  → repeated Transformer blocks
  → next-token logits
  → decoding policy selects a token
  → append token and repeat
  → parser, policy, tools, and downstream action
Figure 1 — The complete LLM request path. This text-native diagram is deliberately kept as selectable, searchable evidence: it places identity and authorization before generation and policy, execution, and audit after generation.
Every arrow is a potential source of changed behavior. A response can change because the application selected different context, an untrusted document entered the prompt, the tokenizer or template changed, earlier instructions were truncated, a model route changed, the decoding configuration changed, or a downstream parser interpreted output differently.
Security consequence: “The model ignored the system prompt” is not yet an incident description. Preserve the serialized prompt or an approved privacy-safe representation, token counts, truncation decisions, model and tokenizer identifiers, decoding configuration, output, parser result, policy decision, and any action taken.
Course rule: The model generates candidate content. The application authenticates identities, authorizes access, validates data, enforces policy, approves actions, and records evidence.
2. The complete LLM request path
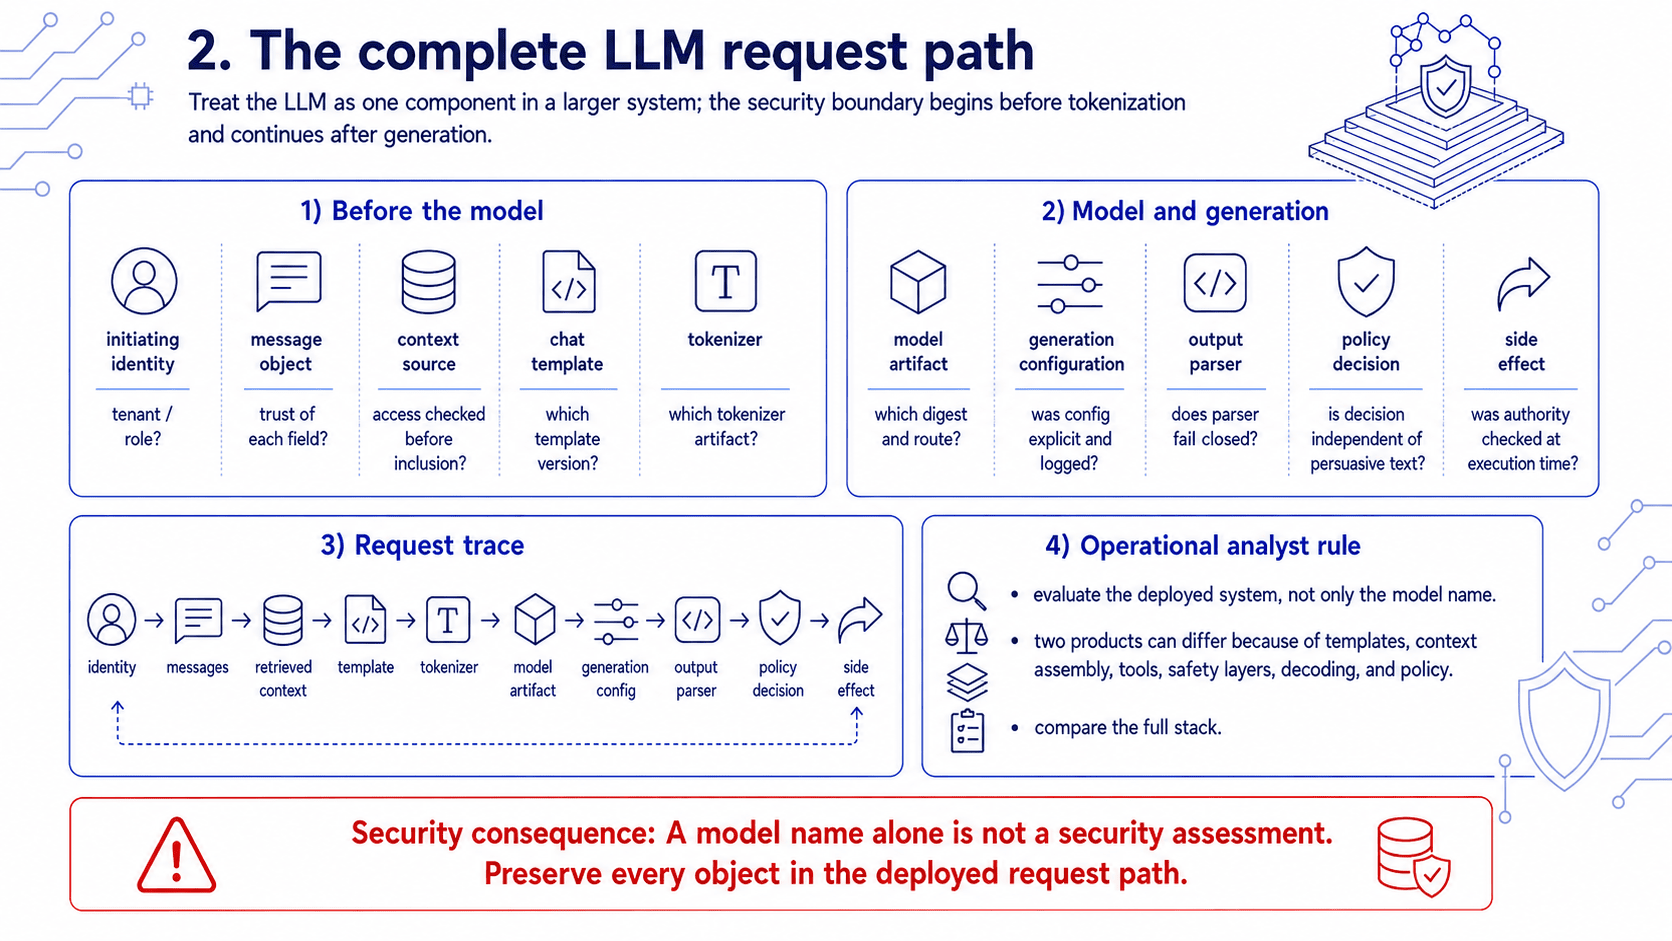
Treat the LLM as one component in a larger system. The security boundary begins before tokenization and continues after generation.
| Object | What it is | Security question |
|---|---|---|
| Initiating identity | User, service, workload, or agent starting the request | Which tenant, role, and authority apply? |
| Message object | Structured role and content supplied by the application | Who created each field, and is it trusted? |
| Context source | Retrieved document, memory, tool result, or policy text | Was access checked before inclusion? |
| Chat template | Serialization rules and special control tokens | Which version produced the actual sequence? |
| Tokenizer | Algorithm and vocabulary mapping text or bytes to IDs | Which artifact, normalization, and special tokens were used? |
| Model artifact | Architecture, parameters, and configuration | Which digest and serving route handled the request? |
| Generation configuration | Temperature, sampling, length, stop, and penalties | Was it explicit, bounded, and logged? |
| Output parser | Code converting text into data or a proposed action | Does it fail closed and validate against a schema? |
| Policy decision | Deterministic allow, deny, transform, or approval rule | Is it independent of persuasive model text? |
| Side effect | Tool call, message, file change, purchase, or access change | Was exact authority checked at execution time? |
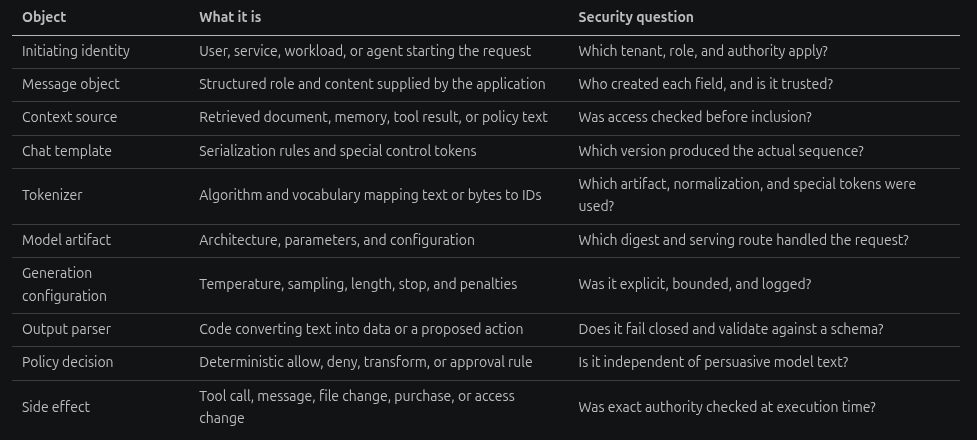
The same base model can behave differently behind two products because their templates, context assembly, tools, safety layers, decoding, and policies differ. Evaluate the deployed system, not only a model name.
3. Tokenization and the model interface
A tokenizer maps text or bytes into token IDs from a versioned vocabulary. Tokens may represent a word, word fragment, punctuation mark, byte sequence, whitespace pattern, or special control marker. Tokenization is reversible only within the tokenizer's defined behavior; it is not a semantic security parser.
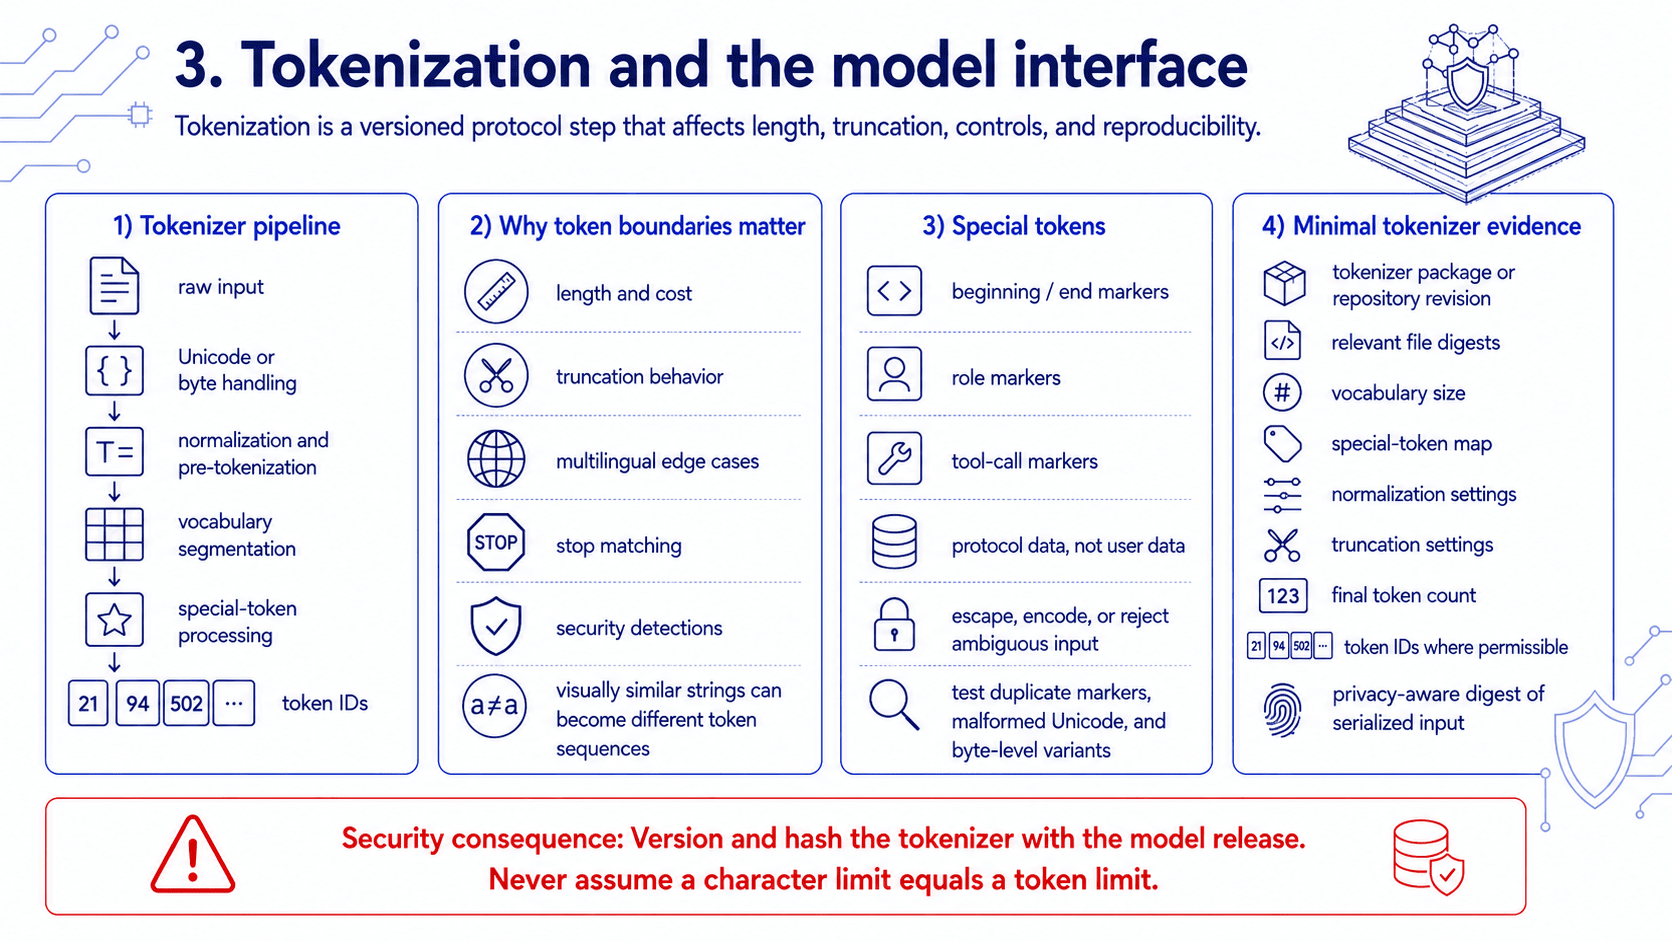
raw input
  → Unicode or byte handling
  → normalization and pre-tokenization
  → vocabulary segmentation
  → special-token processing
  → token IDs
Token boundaries affect length, cost, truncation, multilingual behavior, detection rules, and stop matching. Two visually similar strings may become different token sequences. One token ID can also be interpreted differently if the vocabulary or tokenizer artifact changes.
Security consequence: Version and hash the tokenizer with the model release. Test security controls against token IDs as well as rendered text when token boundaries matter. Never assume a character limit equals a token limit.
Special tokens
Special tokens can mark beginning, end, padding, roles, tool calls, or document boundaries. Whether user text can contain or imitate these markers depends on the tokenizer and template implementation.
Security consequence: Treat reserved control markers as protocol data. Escape, encode, or reject ambiguous input at the serialization boundary. Test duplicate beginning/end markers, embedded role markers, malformed Unicode, and byte-level variants.
Minimal tokenizer evidence
For a reproduced request, retain:
- tokenizer repository or package and immutable revision;
- relevant file digests and vocabulary size;
- special-token map and added tokens;
- normalization and truncation settings;
- the final token count and, where permissible, token IDs; and
- a privacy-aware digest or encrypted capture of the serialized input.
4. Chat templates and instruction serialization
Chat applications usually represent a conversation as structured messages, but a text model consumes a token sequence. A chat template converts roles and content into the format used during model training or instruction tuning.
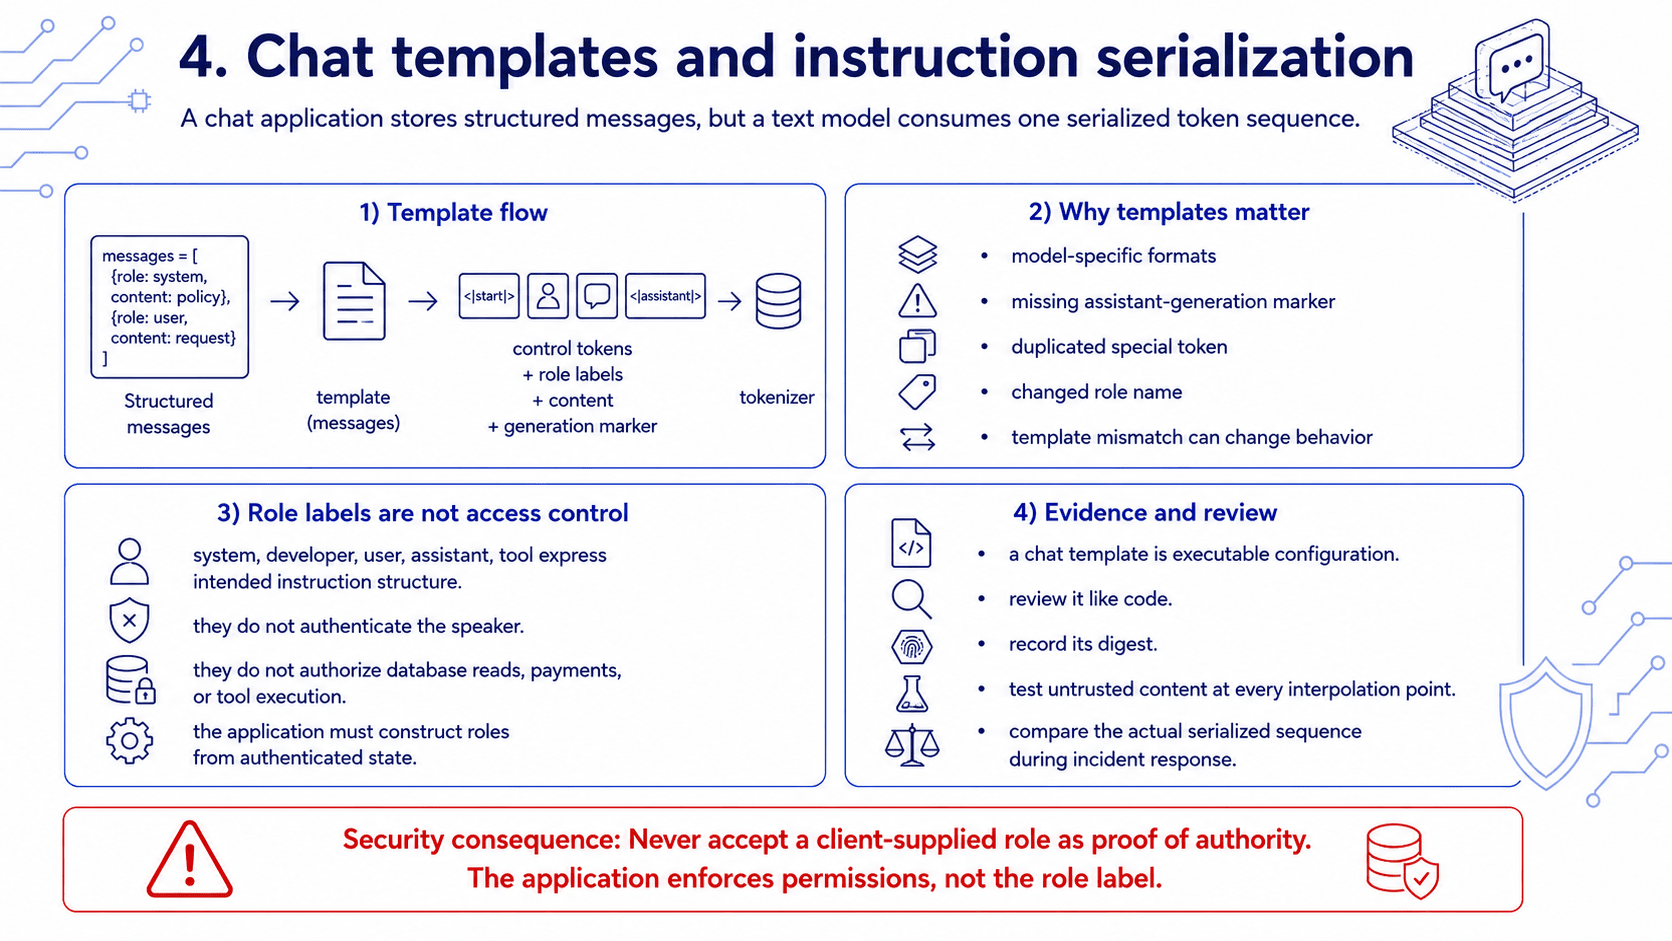
messages = [
  {role: "system", content: system_policy},
  {role: "user", content: user_request}
]

template(messages)
  → control tokens + role labels + content + generation marker
  → tokenizer
Different models trained from similar base checkpoints may require different formats. A missing assistant-generation marker, duplicated special token, changed role name, or template mismatch can reduce performance or change instruction-following behavior.
Security consequence: A chat template is executable configuration and part of the release artifact. Review it like code. Record its digest, test untrusted content at every interpolation point, and compare the actual serialized sequence during incident response.
Role labels are not access-control boundaries
The labels system, developer, user, assistant, tool, or similar names express intended instruction structure to a model. They do not authenticate the speaker and do not enforce tenant or tool permissions.
Security consequence: The application must construct roles from authenticated state. Never accept a client-supplied role as proof of authority. A system message can influence model behavior, but it cannot authorize a database read or a payment.
5. Embeddings and positional information
Each token ID is mapped to a learned vector called a token embedding. The model also needs position information because token embeddings alone do not describe order. Transformer implementations may use learned positional embeddings, fixed encodings, rotary position embeddings, or other mechanisms.
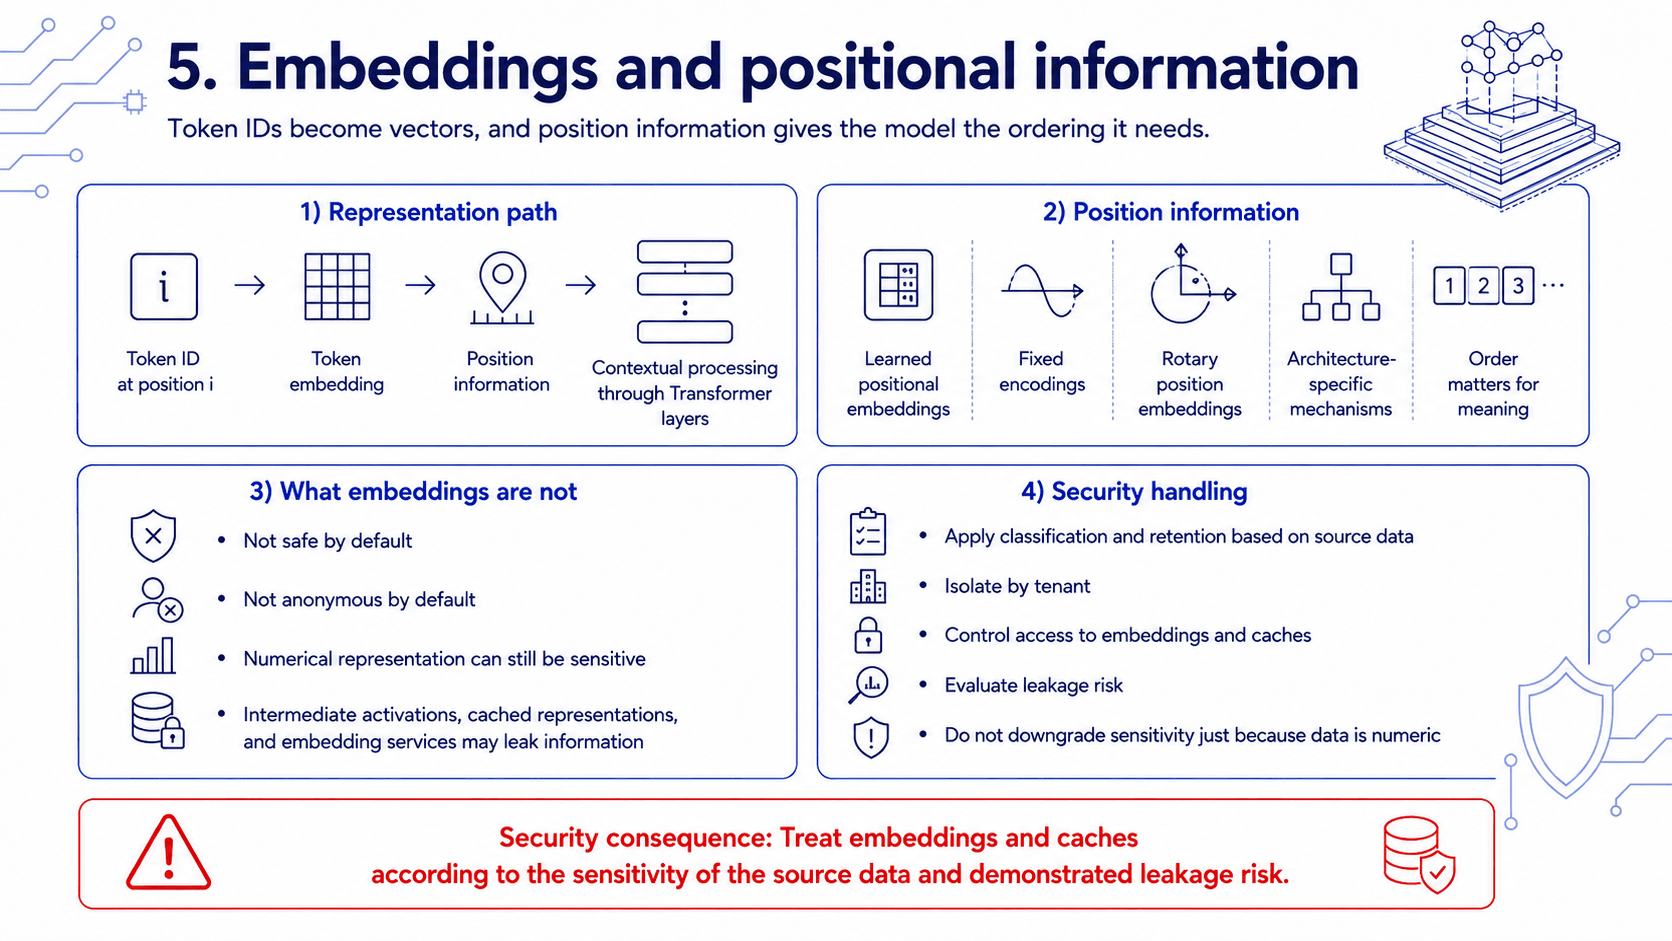
token ID at position i
  → token representation
  + or combined with position information
  → contextual processing through Transformer layers
An embedding is a numerical representation, not a safe or anonymous form of the original content. Intermediate activations, cached representations, and embedding services can remain sensitive.
Security consequence: Apply classification, retention, tenant isolation, and access control to embeddings and caches according to the source data and demonstrated leakage risk. Do not downgrade data merely because it is represented numerically.
6. Self-attention: learned information flow
For each position, an attention head derives a query, key, and value representation. Query–key similarity produces weights, and those weights combine value information. A common conceptual form is:
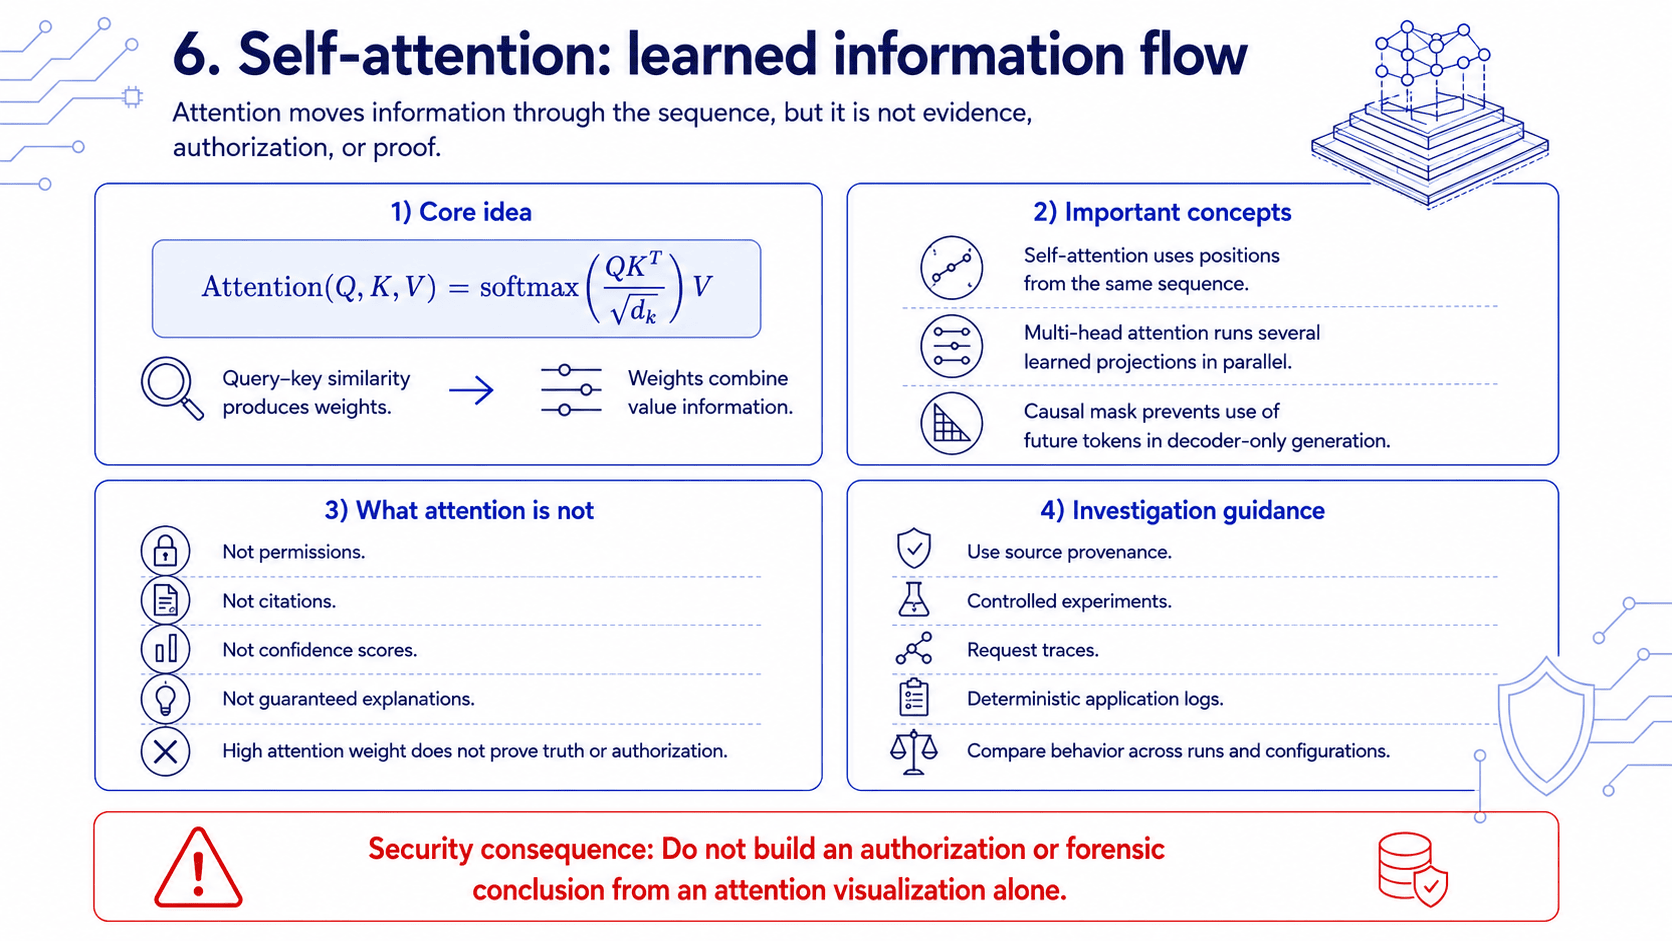
Attention(Q, K, V) = softmax(QKᵀ / √d_k) V
In self-attention, queries, keys, and values are derived from positions in the same sequence. Multi-head attention performs several learned projections in parallel, allowing different patterns of information flow. A causal mask prevents a decoder-only language model from using future tokens when predicting the next token.
Attention weights are not permissions, citations, confidence scores, or guaranteed explanations. High weight does not prove that a source authorized an action or that a generated claim is true.
Security consequence: Do not build an authorization or forensic conclusion from an attention visualization alone. Use source provenance, controlled experiments, request traces, and deterministic application logs.
7. The Transformer block
A modern Transformer block commonly combines attention, a position-wise feed-forward network, residual connections, and normalization. Exact ordering and components vary by architecture.
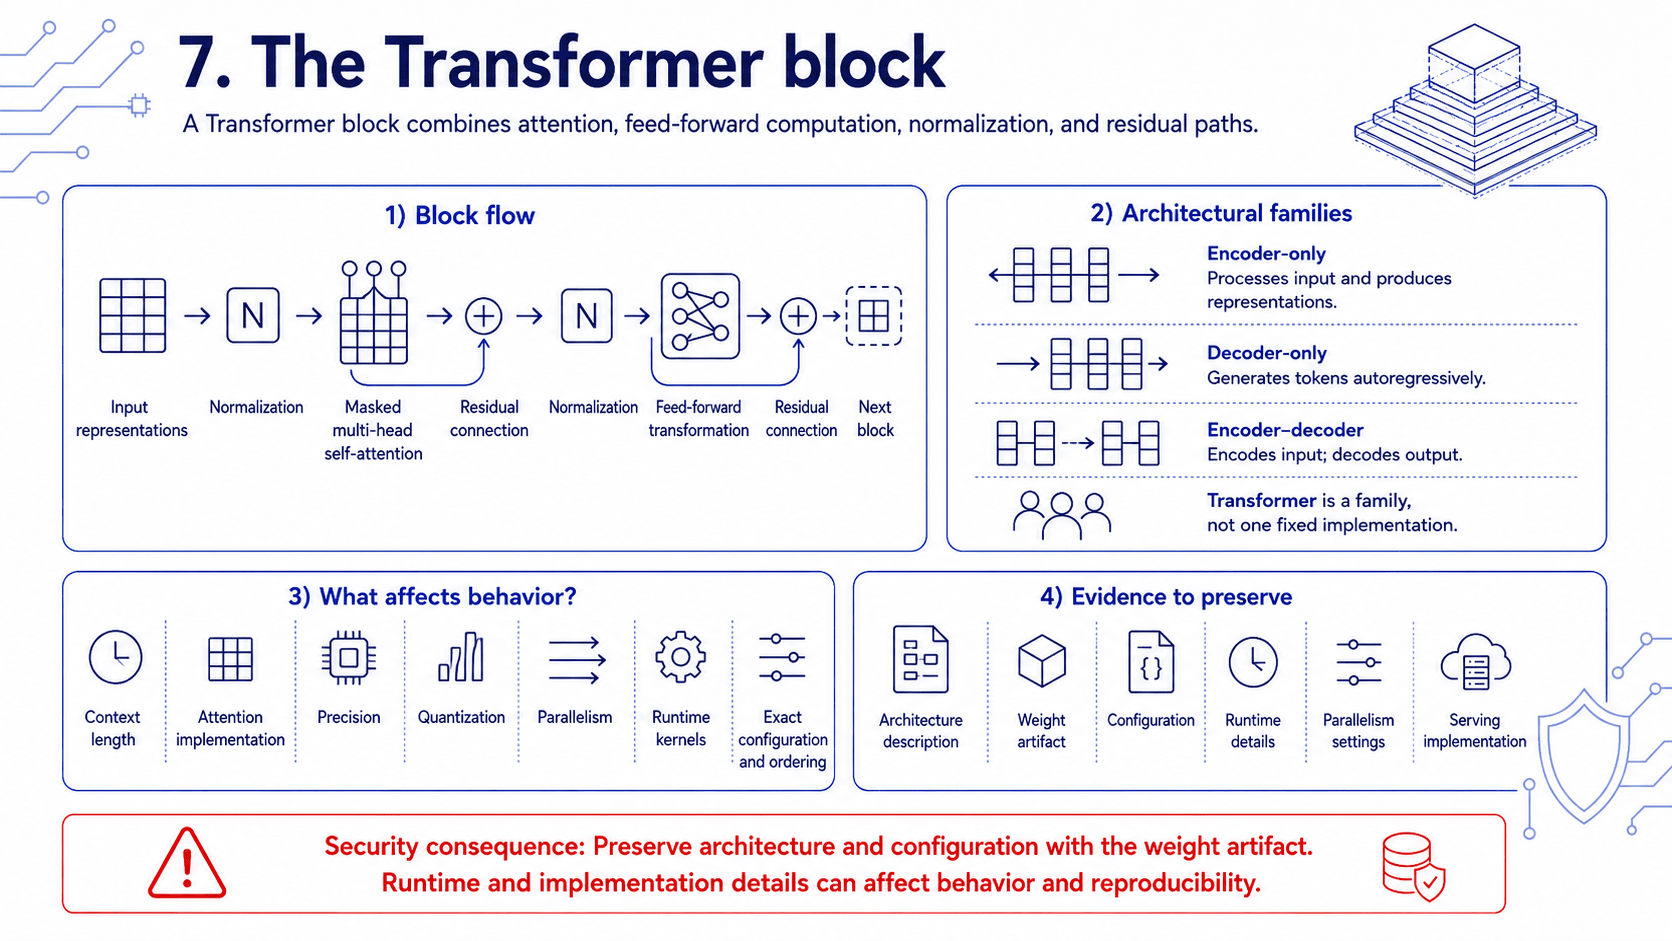
input representations
  → normalization
  → masked multi-head self-attention
  → residual connection
  → normalization
  → feed-forward transformation
  → residual connection
  → next block
The original Transformer used encoder and decoder stacks. Many generative LLMs use a decoder-only, causally masked design; other models use encoder-only or encoder–decoder architectures. “Transformer” therefore names an architectural family, not one fixed implementation.
Security consequence: Preserve the architecture and configuration with the weight artifact. Context length, attention implementation, precision, quantization, parallelism, and runtime kernels can affect behavior and reproducibility.
8. Causal language modeling and next-token prediction
A decoder-only language model estimates a distribution over the next token given previous tokens. Its output layer produces logits—unnormalized scores over the vocabulary. A softmax transformation can convert them into a probability distribution, after which the generation procedure selects a token.
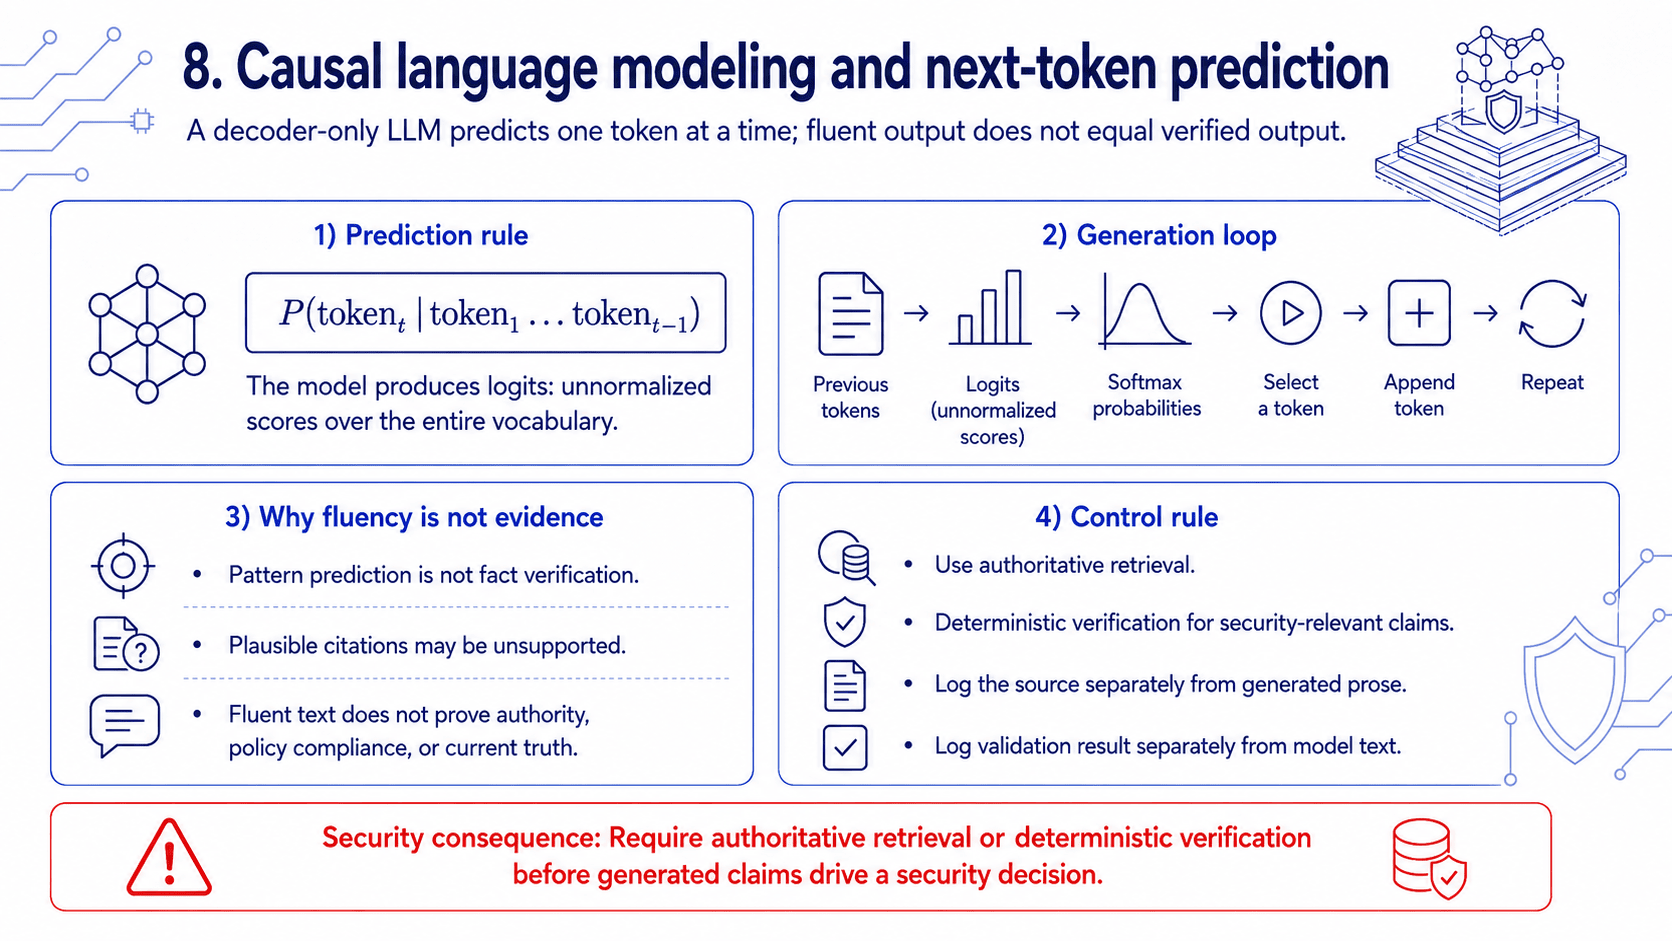
P(token_t | token_1 ... token_t-1)
The selected token is appended and the model runs again. Coherent paragraphs emerge through repeated conditional prediction; the mechanism does not independently retrieve current facts, verify claims, remember a user's legal authority, or understand organizational policy.
Why fluent output is not verified output
Training rewards prediction of patterns in data. Instruction tuning and preference optimization can make responses more useful, but fluency remains distinct from evidence. A plausible citation, hostname, vulnerability ID, command, or policy statement may be unsupported.
Security consequence: Require authoritative retrieval or deterministic verification for claims that drive security decisions. Log the source and validation result separately from generated prose.
9. Context windows, truncation, and KV cache
The context window is the bounded token sequence available to a generation request. It may contain instructions, history, retrieved content, tool schemas, tool results, memory, and output generated so far. Product limits can be lower than the underlying model limit.
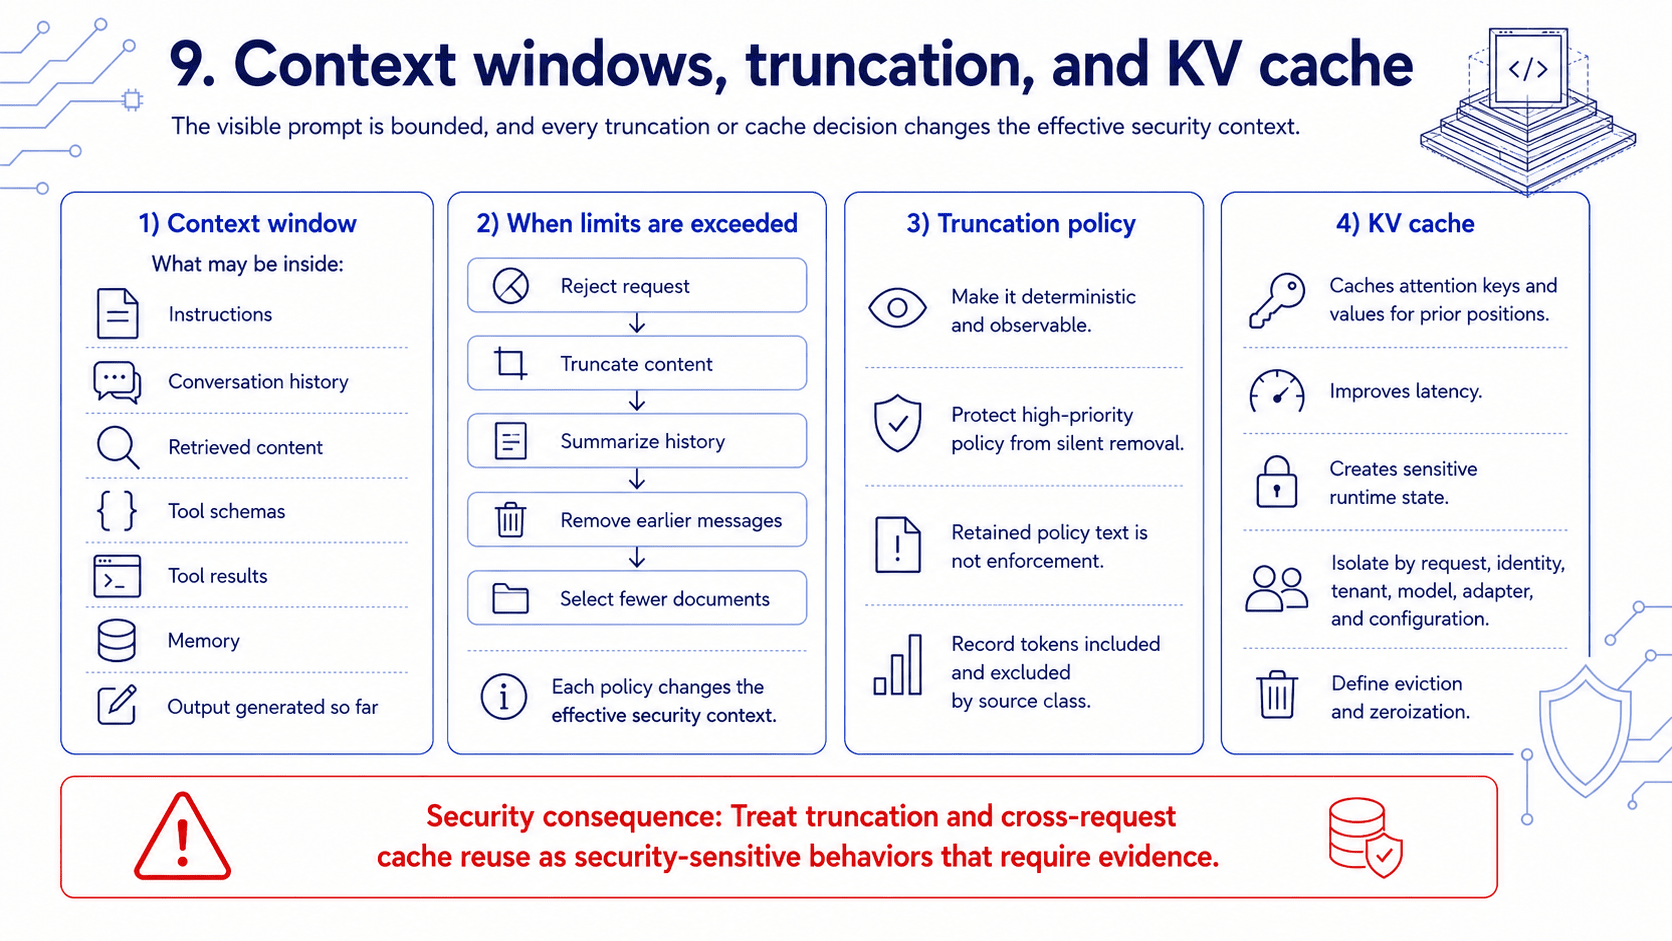
When input plus requested output exceeds a limit, an application may reject the request, truncate content, summarize history, remove earlier messages, or select fewer documents. Each policy changes the effective security context.
Security consequence: Make truncation deterministic and observable. Protect high-priority policy from silent removal, but do not mistake retained policy text for enforcement. Record tokens included and excluded by source class.
KV cache
Autoregressive serving often caches attention keys and values for prior positions so each new token does not recompute the full prefix. Cache reuse improves latency but creates sensitive runtime state.
Security consequence: Isolate cache entries by request, identity, tenant, model, adapter, and relevant configuration. Define eviction and zeroization behavior. Treat cross-request cache reuse as a security-sensitive optimization requiring evidence.
10. Decoding and generation controls
Decoding converts logits into a token choice. The model artifact does not uniquely determine the response.
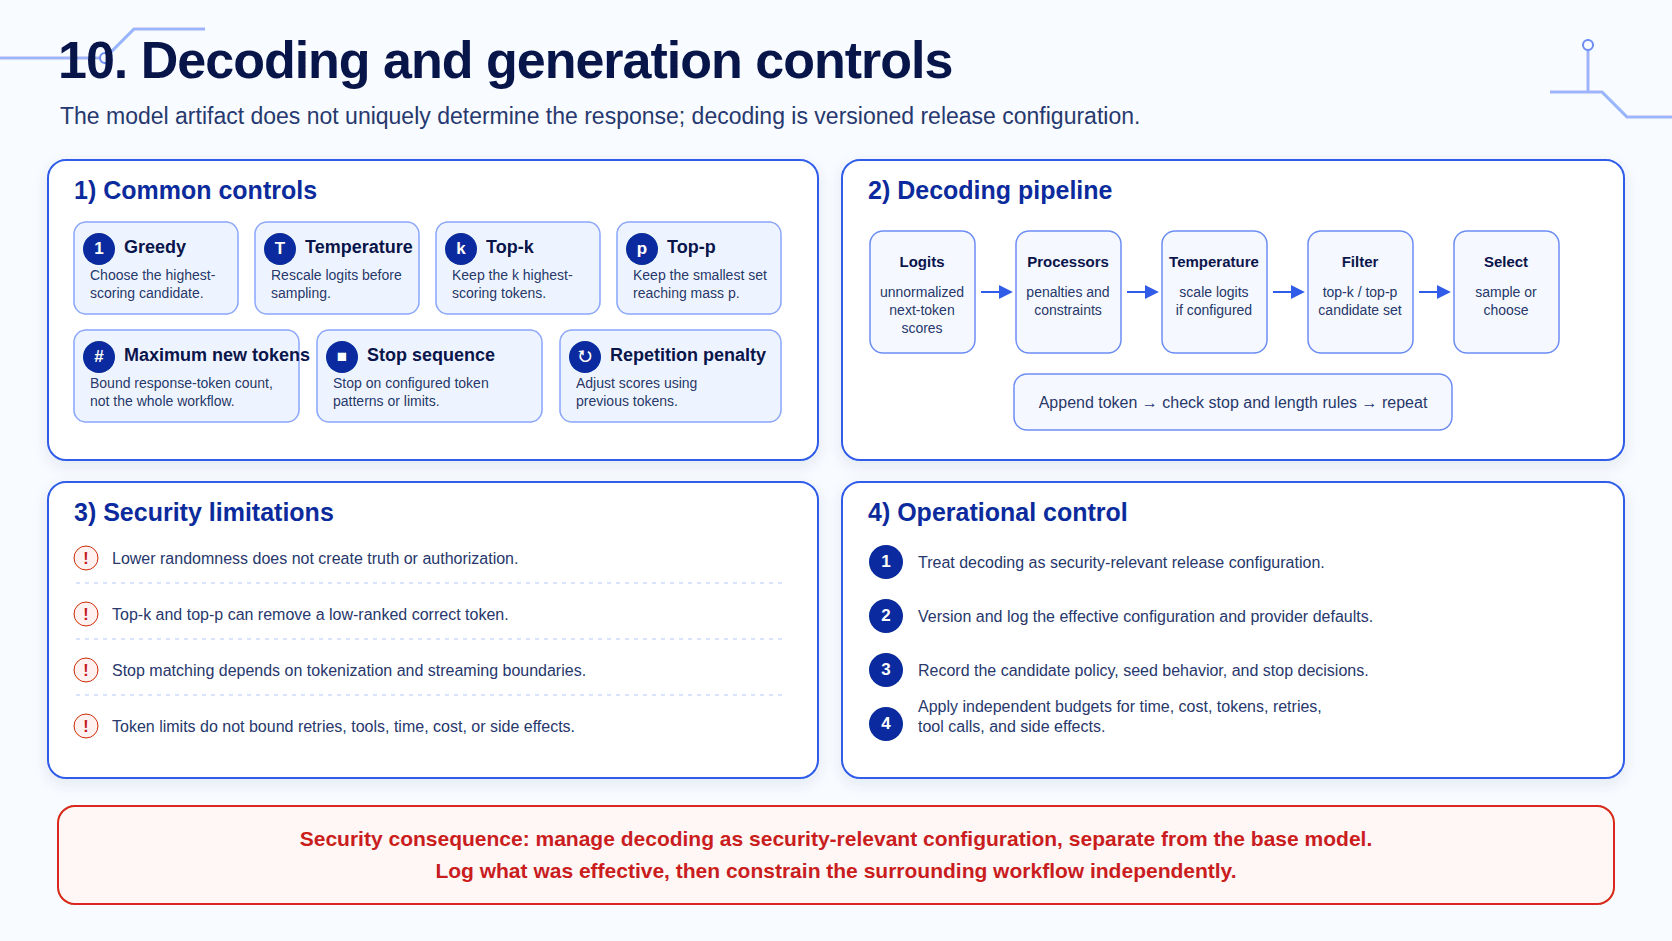
| Control | Mechanism | Security limitation |
|---|---|---|
| Greedy decoding | Select the highest-scoring token | Can still vary across runtimes and does not ensure correctness |
| Temperature | Rescale logits before sampling | Lower values reduce randomness but do not create authorization or truth |
| Top-k | Restrict choices to the k highest-scoring tokens | Can remove a low-ranked correct token |
| Top-p | Use the smallest set reaching cumulative probability p | Candidate set changes at each step |
| Maximum new tokens | Bound response-token count | Does not bound retries, tool loops, or total workflow cost |
| Stop sequence | Stop when configured token patterns appear | Tokenization and streaming boundaries can affect matching |
| Repetition penalty | Change scores based on prior tokens | Can distort structured or security-sensitive output |
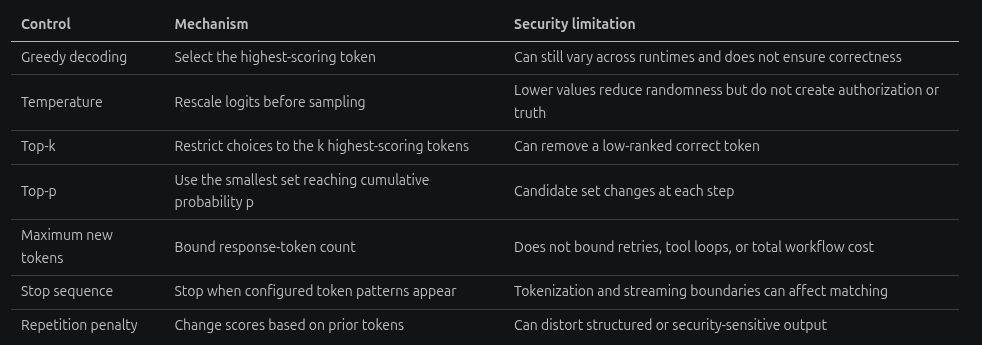
logits
  → processors and penalties
  → temperature
  → top-k / top-p filtering
  → sample or select
  → stop and length rules
Security consequence: Treat decoding as versioned release configuration. Apply independent workflow budgets for time, cost, tokens, retries, tool calls, and side effects.
11. Determinism, reproducibility, and evidence
The same visible prompt can yield a different output because of hidden context, template changes, tokenization, model routing, floating-point behavior, batching, hardware, kernels, sampling, seed handling, or provider updates. A temperature of zero is not a universal service-level guarantee of identical text.
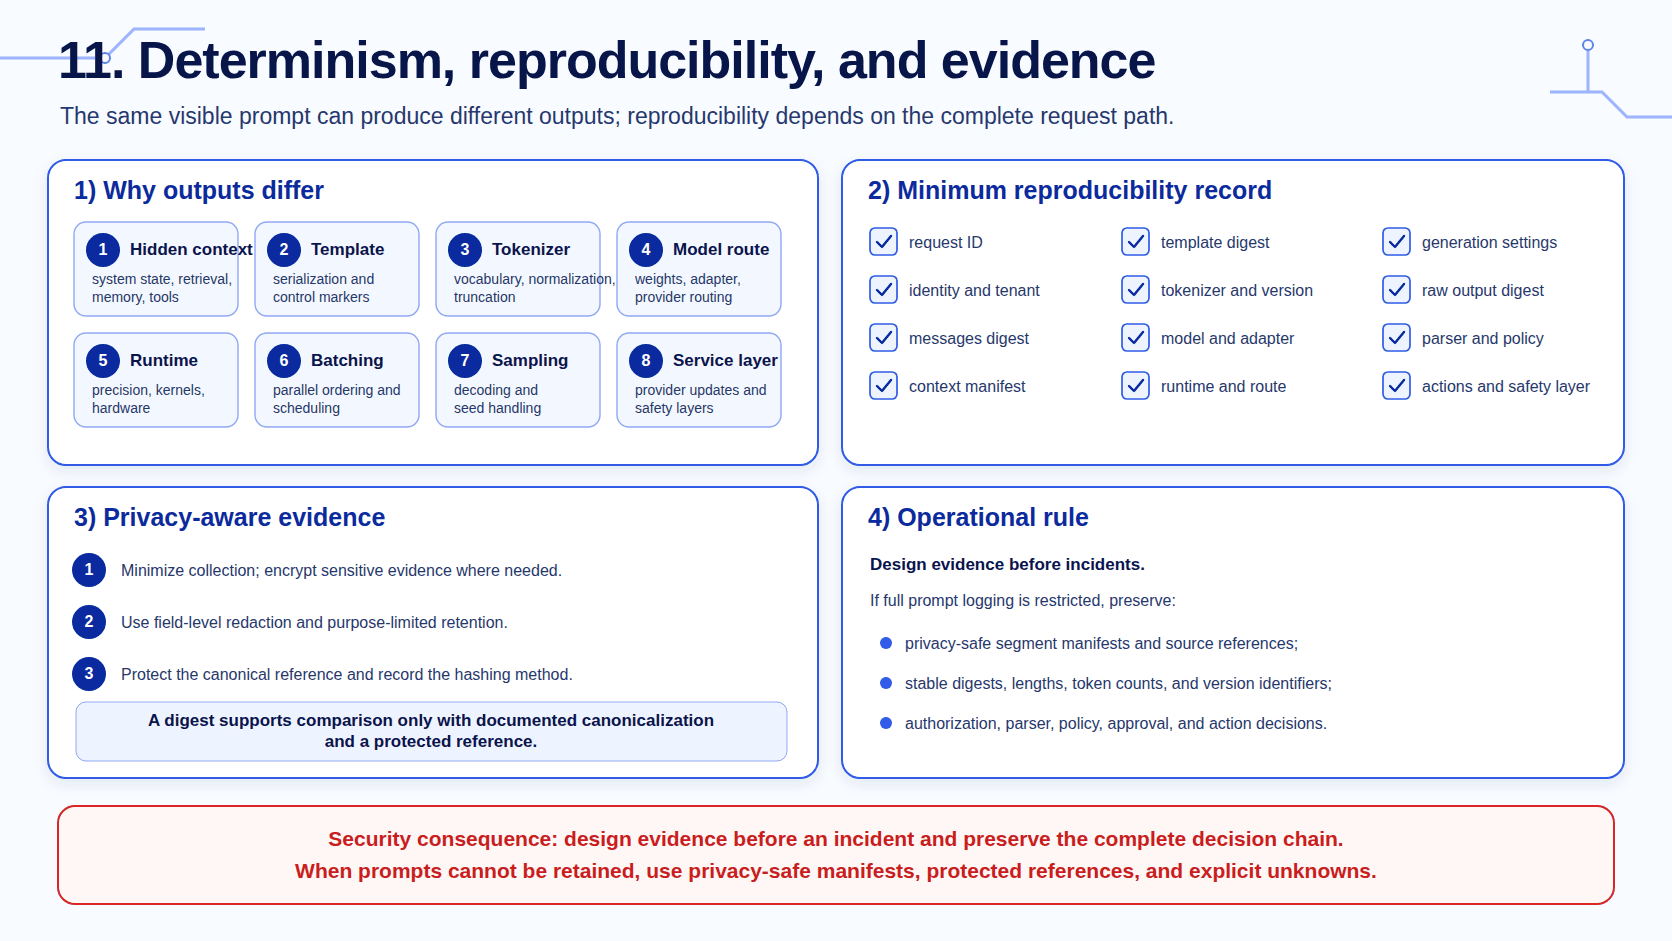
Minimum reproducibility record
request_id: immutable identifier
initiating_identity: pseudonymous or access-controlled reference
tenant: tenant identifier
messages_digest: digest of canonical structured messages
context_manifest: source IDs, versions, ACL decisions, order, and token counts
template_digest: immutable chat-template digest
tokenizer: artifact ID and digest
model: artifact or provider model-version identifier
adapter: identifier and digest, if used
runtime: provider or local runtime version
generation: temperature, top_p, top_k, max_tokens, stop, seed
output_digest: digest of raw generated bytes
parser_and_policy: versions and decisions
actions: exact proposed, approved, denied, and executed actions
safety_layer: guardrail or filter identifiers, versions, and decisions
Sensitive prompts and outputs may require encryption, minimization, field-level redaction, or shorter retention. A digest proves equality only when the canonicalization method and protected original are available for authorized investigation.
Security consequence: Design evidence before an incident. If privacy policy prevents full prompt logging, retain a manifest of trusted/untrusted segments, stable digests, lengths, token counts, source references, and authorization decisions.
12. Structured output is not authorization
Models can be prompted or constrained to produce JSON, XML, SQL, code, or tool-call arguments. Grammar-constrained generation and schema validation improve syntax. They do not prove semantic correctness, benign intent, object-level authorization, or safe side effects.
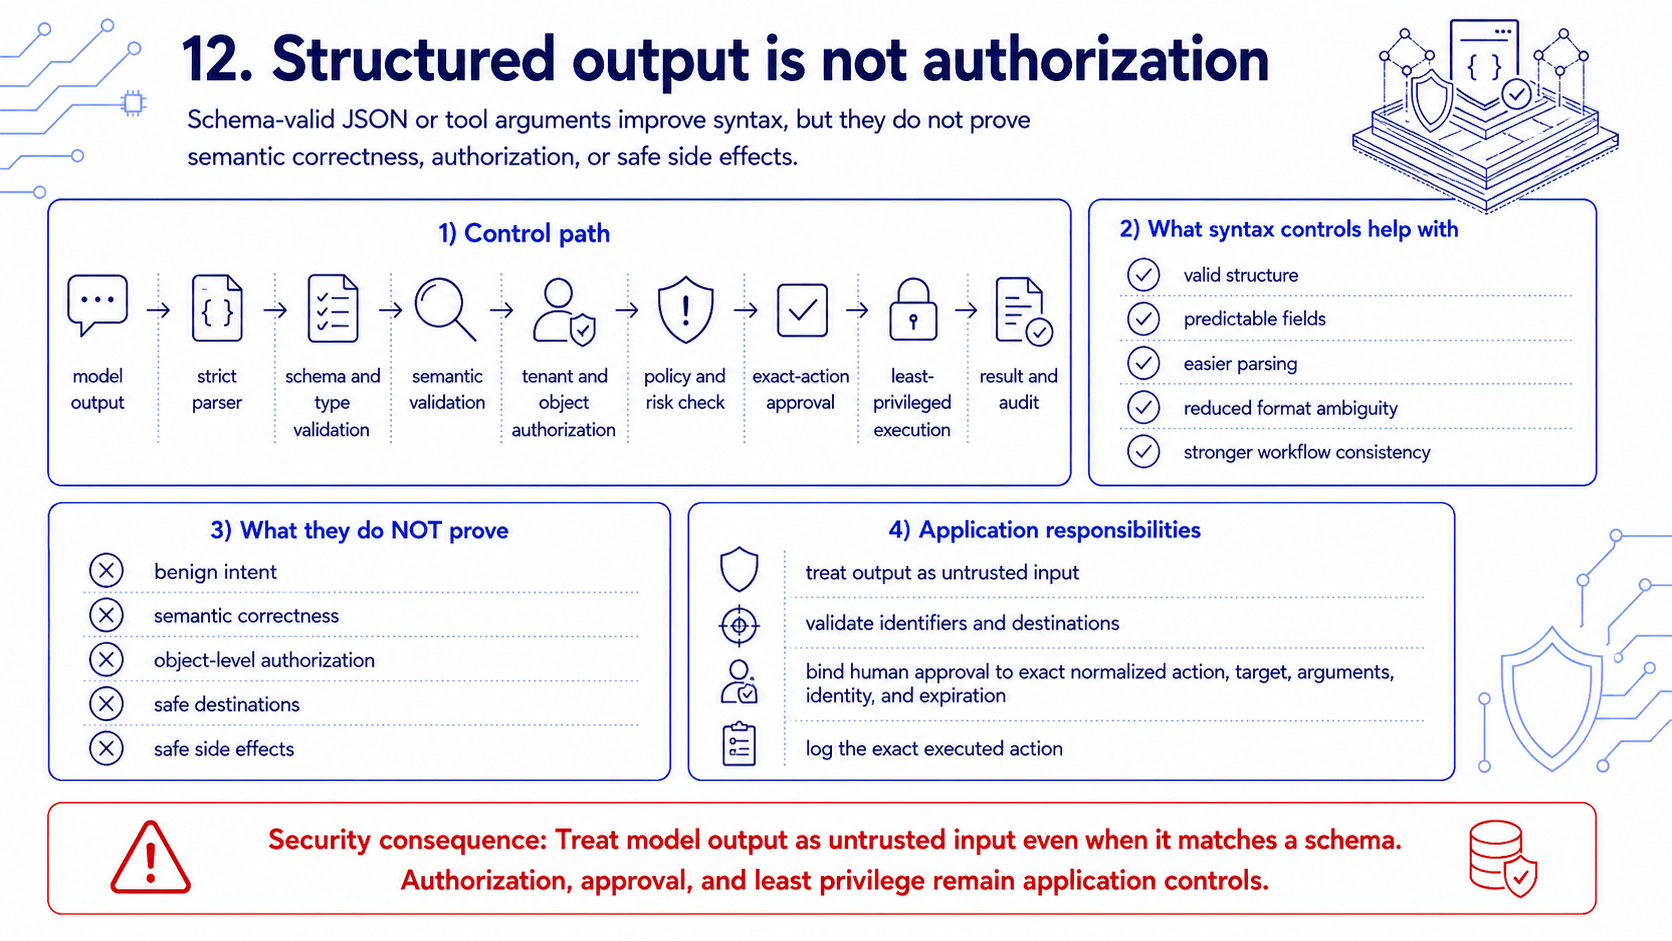
model output
  → strict parser
  → schema and type validation
  → semantic validation
  → tenant and object authorization
  → policy and risk check
  → exact-action approval when required
  → execution with least-privileged identity
  → result and audit record
Figure 2 — From model output to authorized action. Syntax validation is only the first control; semantic validation, authorization, approval, least privilege, and audit remain application responsibilities.
Security consequence: Treat model output as untrusted input even when it matches a schema. Bind human approval to the exact normalized action, target, arguments, identity, and expiration—not to a natural-language summary.
13. Prompt injection and instruction conflicts
Prompt injection is an attack or test in which adversarially chosen input attempts to change a generative AI system's behavior contrary to the application owner's intent. In direct prompt injection, the adversary supplies instructions through an interactive input. In indirect prompt injection, instructions arrive through data the application retrieves or processes, such as a web page, email, document, issue, tool result, or memory entry. In triggered prompt injection, planted instructions activate only when a later phrase, context, identity, time, user action, or system event satisfies the trigger condition.
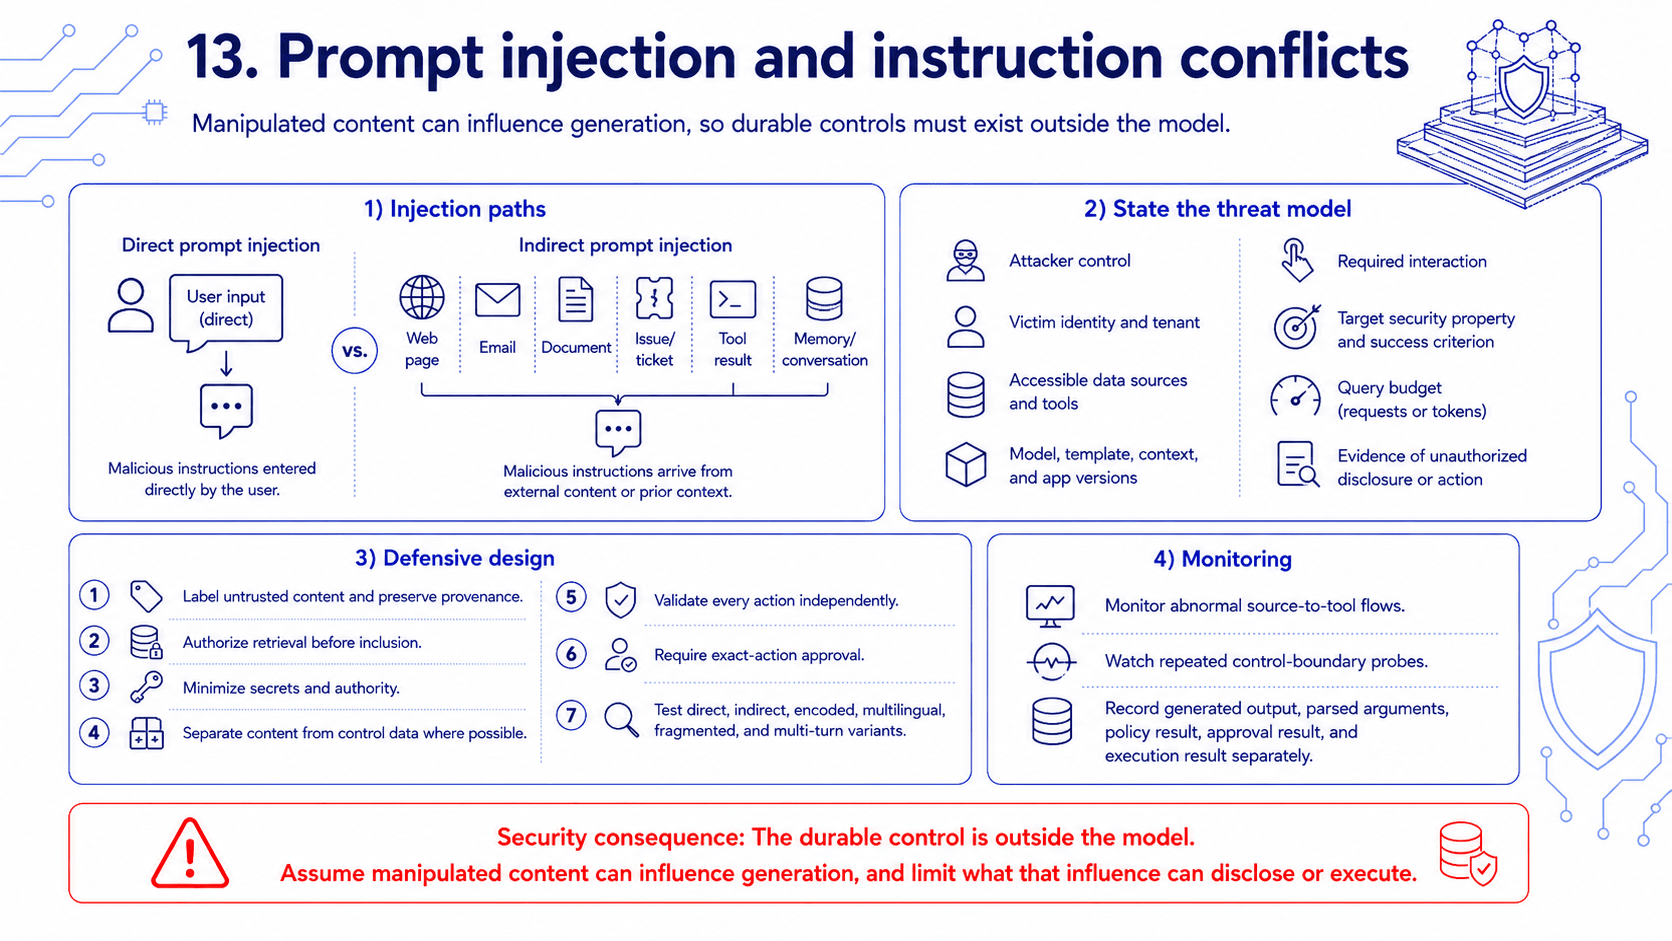
Prompt injection is not ordinary SQL injection: the model is designed to interpret natural-language content as potential instruction. Quoting, delimiters, role text, and “ignore previous instructions” warnings may influence behavior but do not create a hard security boundary.
State the threat model
Record:
- attacker control over direct input or external content;
- victim identity and tenant;
- accessible data sources and tools;
- model, template, context, and application versions;
- required user interaction;
- target security property and success criterion;
- number of attempts or query budget; and
- evidence connecting generated output to an unauthorized disclosure or action.
Defensive design
- Keep untrusted content labeled and provenance-linked.
- Authorize retrieval before content enters context.
- Minimize secrets and authority available to the model path.
- Separate content processing from control data where architecture permits.
- Validate every proposed action independently.
- Require exact-action approval for material side effects.
- Test direct, indirect, encoded, multilingual, fragmented, and multi-turn variants.
- Monitor abnormal source-to-tool flows and repeated control-boundary probes.
Security consequence: The durable control is outside the model. Assume manipulated content can influence generation; limit what that influence can disclose or execute.
14. Extraction, leakage, and sensitive context
An attacker may attempt to obtain system instructions, hidden context, private retrieved data, memorized training examples, model behavior, or proprietary parameters. These are different targets and require different evidence.
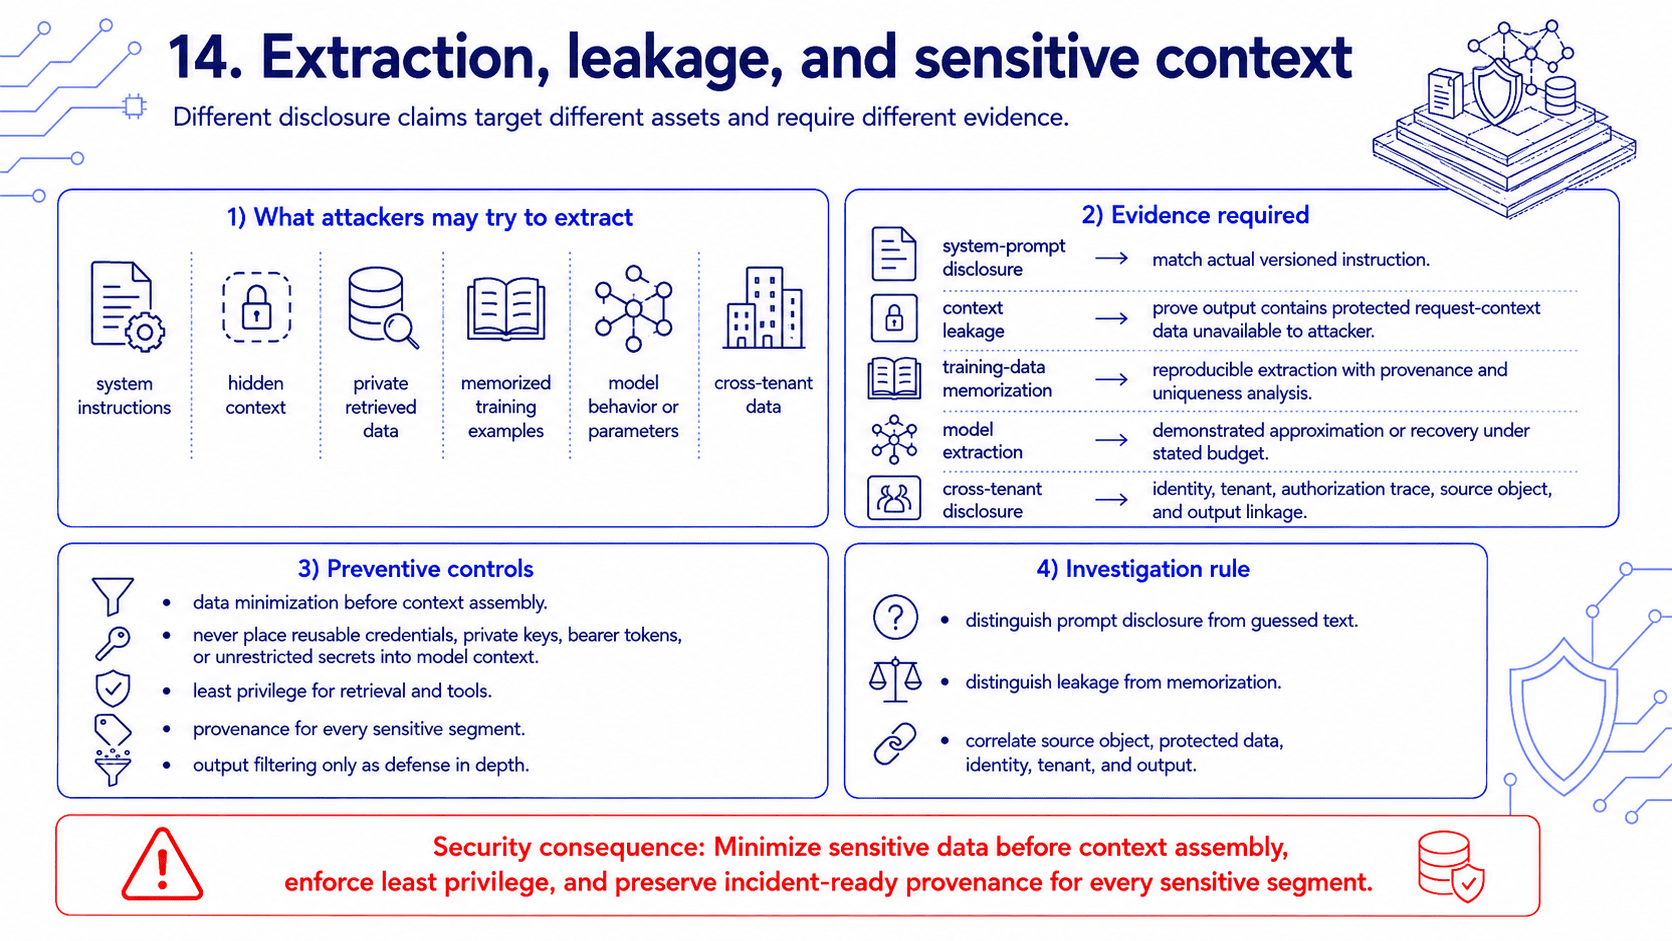
| Claim | Required evidence |
|---|---|
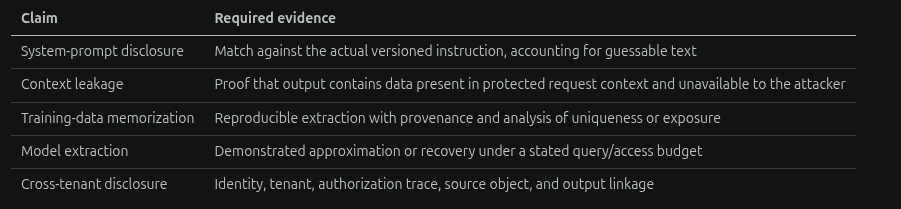
| System-prompt disclosure | Match against the actual versioned instruction, accounting for guessable text |
| Context leakage | Proof that output contains data present in protected request context and unavailable to the attacker |
| Training-data memorization | Reproducible extraction with provenance and analysis of uniqueness or exposure |
| Model extraction | Demonstrated approximation or recovery under a stated query/access budget |
| Cross-tenant disclosure | Identity, tenant, authorization trace, source object, and output linkage |
Avoid putting reusable credentials, private keys, bearer tokens, or unrestricted secrets into model context. A system prompt is configuration, not an appropriate secret store.
Security consequence: Apply data minimization before context assembly, output filtering only as defense in depth, least privilege to retrieval and tools, and incident-ready provenance for every sensitive segment.
15. CTI case study: indirect prompt injection
Disclosed case: EchoLeak
EchoLeak anchors this pattern in a disclosed production-system vulnerability. Aim Security researchers reported a zero-click indirect prompt-injection chain affecting Microsoft 365 Copilot; Microsoft assigned CVE-2025-32711, remediated the issue, and stated that no customer action was required. MITRE ATLAS records the research as case study AML.CS0059. The ATLAS case record says a malicious email could enter Copilot's retrieval context, influence the generated response, and use rendered Markdown image behavior to create an outbound exfiltration path.
In this case, zero-click means that the victim did not need to open the malicious email or select an attacker-supplied link. A later, ordinary Copilot interaction acted as the trigger after the content had entered the retrieval path; it does not mean that the system produced an effect without any subsequent request or event.
This evidence supports a disclosed and reproduced capability against the affected design. It does not establish exploitation in the wild, universal behavior across Copilot versions, or compromise of every tenant. Preserve that distinction when turning a case study into a detection or architectural requirement.
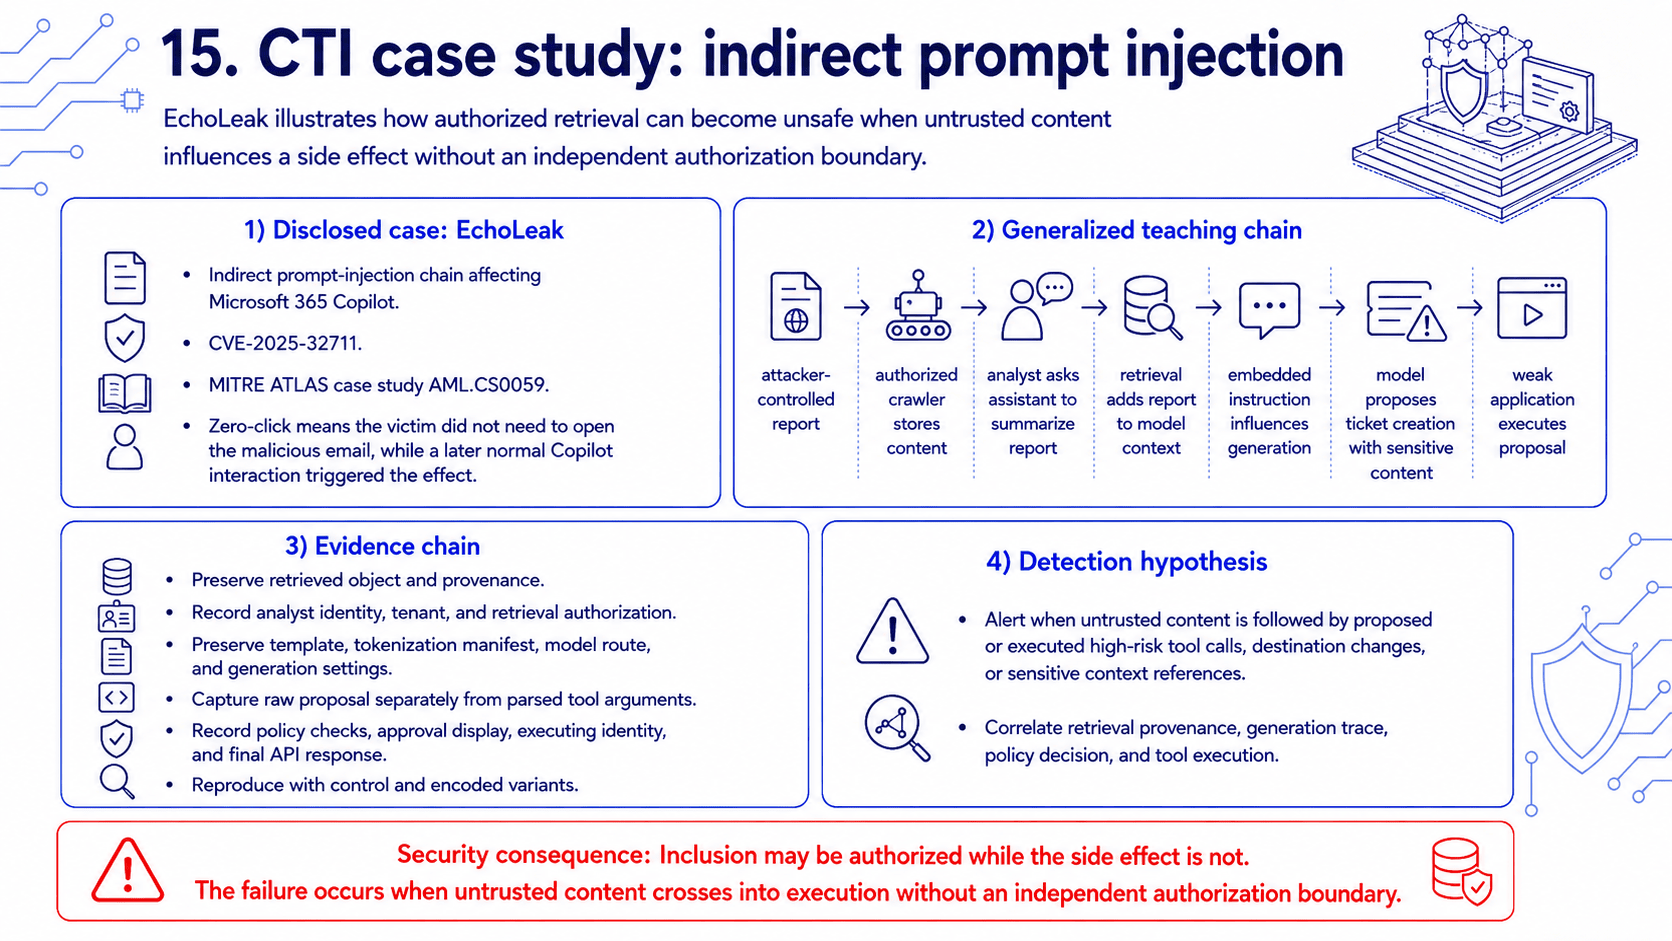
The generalized teaching scaffold below changes the product and side effect deliberately. Consider a synthetic, course-only security assistant that reads external incident reports and can create tickets. A report contains hidden or visible text instructing the assistant to copy prior private context into a ticket controlled by the attacker.
attacker-controlled report
  → authorized crawler stores content
  → analyst asks assistant to summarize report
  → retrieval adds report to model context
  → embedded instruction influences generation
  → model proposes ticket creation with sensitive content
  → weak application executes proposal
Figure 3 — Generalized indirect prompt-injection chain. EchoLeak used email retrieval and response rendering; the synthetic ticket workflow changes those components so learners can reason about the underlying trust-boundary failure without replaying a real exploit.
The report's inclusion may be authorized while the ticket content and destination are not. The security failure occurs when untrusted content influences a side effect without an independent authorization and policy boundary. This general pattern was established in earlier application-integrated prompt-injection research by Greshake et al.; the EchoLeak disclosure provides a later production-system case with a CVE and a published evidence chain.
Evidence chain
- Preserve the retrieved object, version, parser output, and provenance.
- Record the authenticated analyst, tenant, request, and retrieval authorization.
- Preserve the template, tokenization manifest, model route, and generation configuration.
- Capture the raw proposal separately from the parsed tool arguments.
- Record policy checks, approval display, executing workload identity, and final ticket API response.
- Reproduce against a benign control document and encoded variants.
- Report whether the result was generated text, blocked proposal, approved action, or executed unauthorized action.
Detection hypothesis
Alert or investigate when content from an untrusted source is followed by a proposed or executed high-risk tool call that references sensitive context, changes destination, or exceeds the initiating user's normal workflow. Correlate retrieval provenance, generation trace, policy decision, and tool telemetry.
16. Controls, ATLAS mapping, and analyst exercise
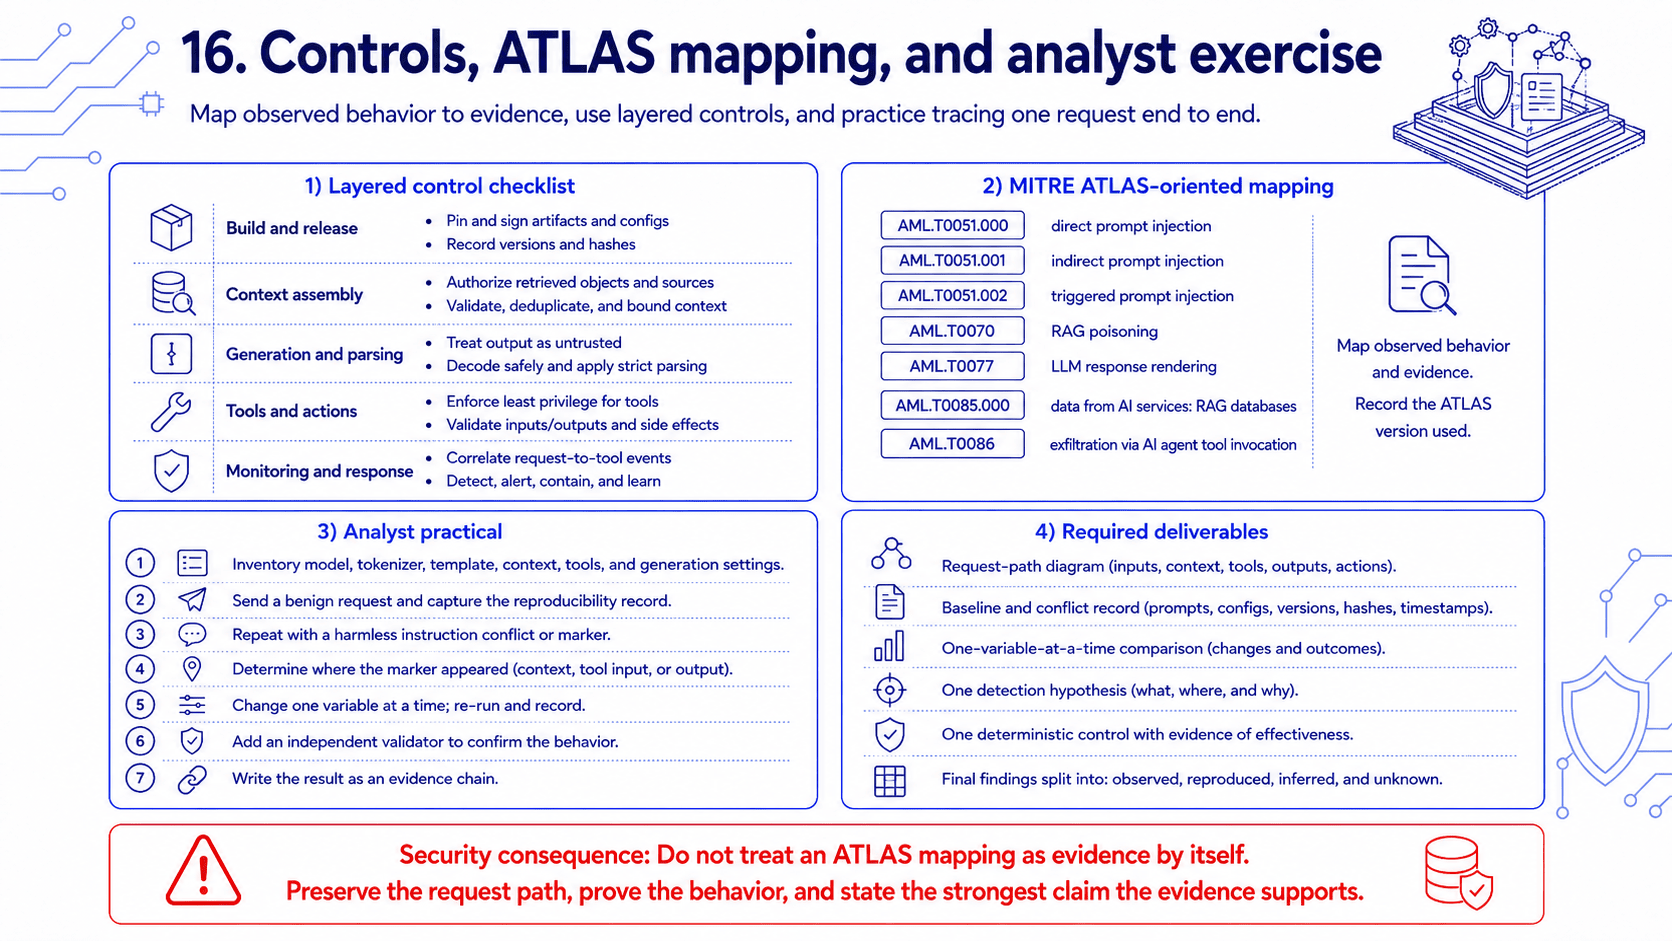
Layered control checklist
Build and release
- Pin model, tokenizer, template, adapter, runtime, and generation configuration.
- Sign artifacts and preserve provenance, evaluation records, and approval.
- Test role serialization, special tokens, truncation, stop handling, and parser failure.
Context assembly
- Authenticate the initiating identity and preserve tenant context.
- Authorize every retrieved object before inclusion.
- Label source, trust, sensitivity, version, and parser for each segment.
- Minimize secrets and enforce deterministic context budgets.
Generation and parsing
- Bound input, output, cost, time, retries, and concurrency.
- Treat output as untrusted data.
- Parse strictly and validate schema, semantics, destinations, and identifiers.
- Keep safety filters observable and versioned.
Tools and actions
- Enforce least privilege with a scoped workload identity.
- Authorize every object and operation at execution time.
- Require exact-action approval for material side effects.
- Make retries idempotent and log proposed, approved, denied, and executed actions separately.
Monitoring and response
- Correlate request, context provenance, model route, output, policy, and tool events.
- Detect unusual source-to-tool flows, destination changes, secret patterns, and repeated probes.
- Support rapid model, template, tool, connector, and content-source rollback.
- Maintain privacy-aware evidence retention and an incident reproduction fixture.
MITRE ATLAS-oriented mapping
The official ATLAS release page listed collection version 2026.07 as latest during the completion review on 31 August 2026; the corresponding immutable Git tag is v2026.07. This chapter records that collection version separately from the YAML data-format version and links the release plus version-pinned YAML evidence.
| ATLAS ID and title in 2026.07 | Chapter connection | Evidence required before mapping |
|---|---|---|
AML.T0051.000 — LLM Prompt Injection: Direct | Adversary supplies the instruction through the interactive input | Original request, identity, template, output, and protected boundary affected |
AML.T0051.001 — LLM Prompt Injection: Indirect | Separate data channel is ingested by the LLM | Retrieved object, source provenance, parser output, context inclusion, and generated result |
AML.T0051.002 — LLM Prompt Injection: Triggered | Later user action or event activates a planted instruction | Infiltration event, activation trigger, request trace, and resulting behavior |
AML.T0070 — RAG Poisoning | Manipulated content is indexed and later retrieved | Indexed object, index version, retrieval trace, relevance, and source authorization |
AML.T0077 — LLM Response Rendering | Rendered output creates an external request containing protected data | Raw model output, renderer behavior, outbound request, destination, and protected value linkage |
AML.T0085.000 — Data from AI Services: RAG Databases | AI service retrieves sensitive organizational information | Caller and tenant, source object, ACL decision, retrieved content, and output linkage |
AML.T0086 — Exfiltration via AI Agent Tool Invocation | A write-capable tool carries protected data to an adversary-controlled destination | Proposed arguments, policy decision, executing identity, API result, destination, and received data |
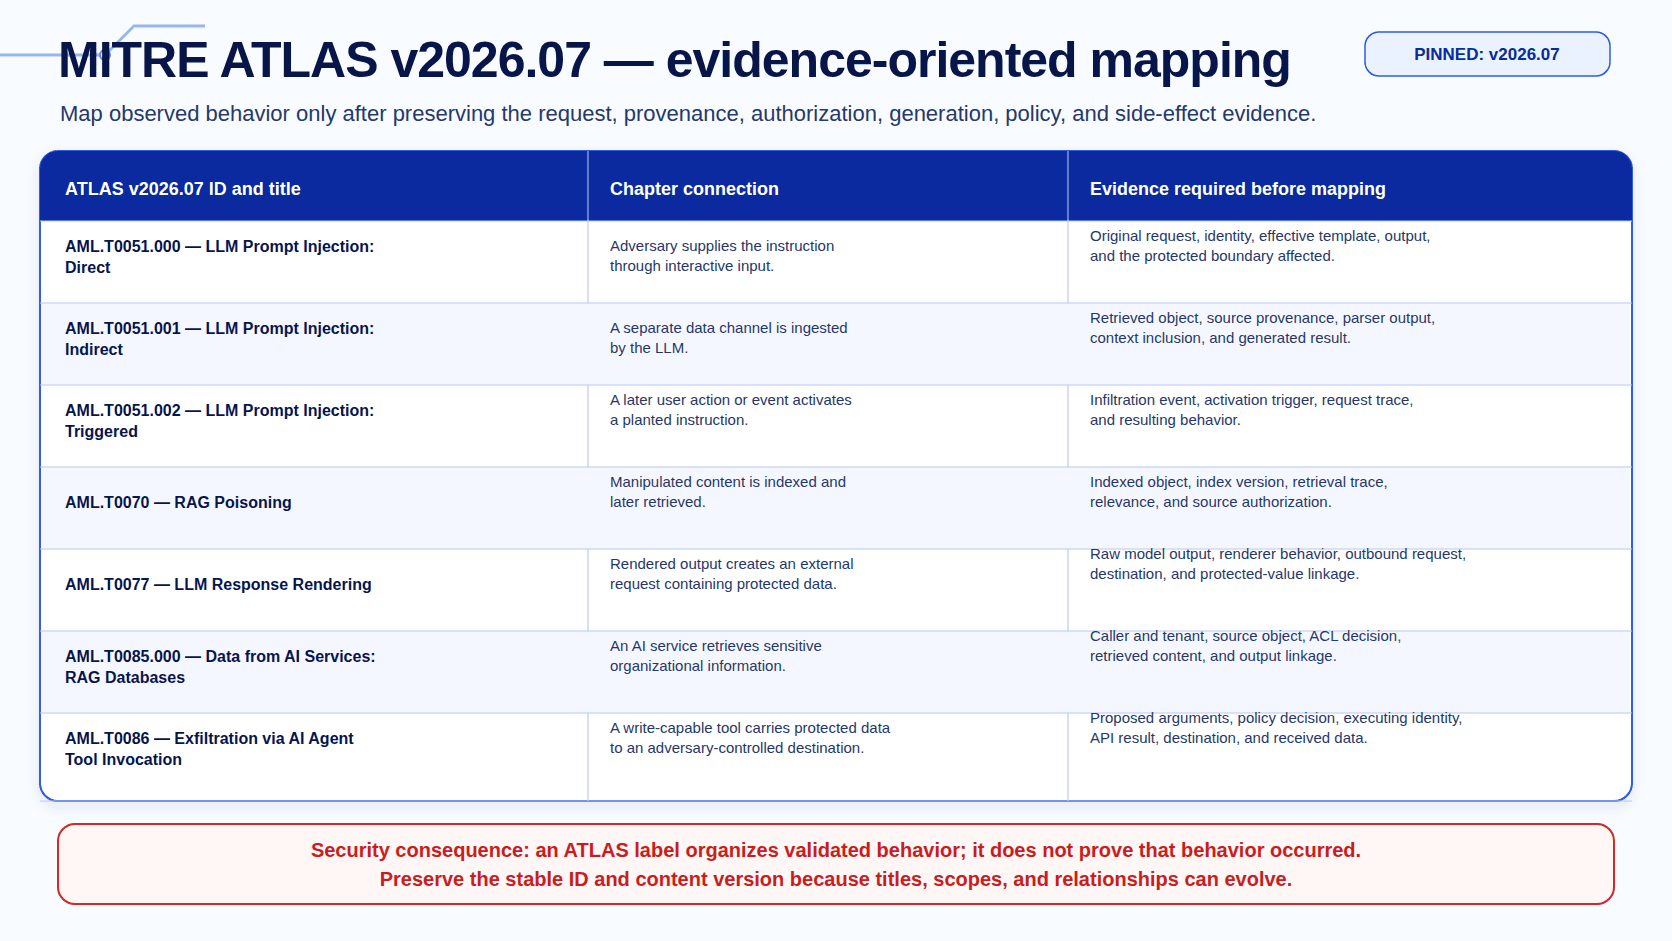
EchoLeak's ATLAS 2026.07 case record maps specific steps to AML.T0051.002, AML.T0070, AML.T0077, and AML.T0085.000, among other techniques. That case mapping does not make the same IDs correct for every prompt-injection test.
Do not force every failed instruction-following test into an ATT&CK or ATLAS technique. Map observed attacker behavior and evidence, and record the ATLAS version used.
Analyst practical: trace one request
Choose a course-owned or otherwise authorized local test application. Do not use production secrets or unauthorized targets. The dedicated Chapter 4 lab fixture is not yet published; until it is available, use an isolated disposable application that has no external side effects, or complete the exercise as a paper architecture trace using the synthetic ticket workflow above.
- Inventory the model, tokenizer, template, context sources, tools, and generation configuration.
- Send a benign request and capture the minimum reproducibility record.
- Repeat with a document containing a harmless instruction conflict, such as a request to output a fixed test marker.
- Determine whether the marker entered retrieved content, serialized context, generated text, parsed arguments, or an executed action.
- Change one variable at a time: document placement, encoding, truncation pressure, template, model, or policy.
- Add an independent action validator and repeat.
- Write the result as an evidence chain, not as “the LLM was hacked.”
Required deliverables
Complete the Chapter 4 request-trace assessment in the Module 00 workbook and submit one concise evidence pack containing:
- A request-path diagram showing identity, context sources, serialization, tokenizer, model route, generation settings, parser, policy, and any available tool boundary.
- A baseline record and one harmless instruction-conflict record, including stable artifact or provider versions and privacy-safe input/output evidence.
- A comparison that changes one variable at a time and distinguishes generated text, parsed proposal, policy decision, approval, and executed action.
- One detection hypothesis with required telemetry, expected benign cases, and a stated false-positive risk.
- One recommended deterministic control and evidence showing whether it operated as intended.
- A final finding divided into observed, reproduced, inferred, and unknown statements.
Assessment rubric
| Criterion | Points | Full-credit standard |
|---|---|---|
| Scope and safe execution | 10 | Names the authorized system, uses a harmless marker, and excludes secrets and third-party data. |
| Request-path accuracy | 20 | Separates identity, context, template, tokenizer, model, decoding, parser, policy, and action. |
| Reproducibility record | 20 | Preserves sufficient versions, digests, settings, provenance, and outputs to repeat the test. |
| Evidence reasoning | 20 | Clearly separates observed facts, reproduced behavior, inference, alternatives, and unknowns. |
| Control and detection design | 20 | Proposes an independently enforced control and a telemetry-backed detection hypothesis with limitations. |
| Communication | 10 | Uses bounded language and does not equate model output with authorization, execution, or verified impact. |
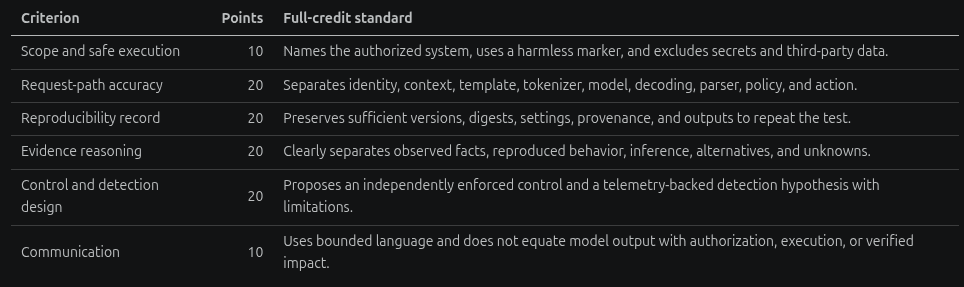
Passing standard: 70/100, with at least half credit in every criterion. Revise any submission that uses unauthorized data, claims impact from generated text alone, omits the effective template or generation configuration, or treats an ATLAS mapping as evidence by itself.
You have completed this chapter when you can reconstruct why an LLM-enabled application produced a result, identify which security boundary accepted or rejected it, and state the strongest claim the preserved evidence supports.
Knowledge check
- Why can two applications using the same model produce different security outcomes?
- Why is a role label not an authorization boundary?
- What does a causal attention mask prevent?
- Which generation settings must be recorded for reproducibility?
- Why does schema-valid JSON remain untrusted?
- What evidence distinguishes prompt disclosure from guessed prompt content?
- Where should authorization occur for retrieved content and tool execution?
- Which event proves impact: generated text, parsed proposal, approved action, or executed action?
- Which identifiers and isolation attributes must be part of a safe cross-request KV-cache design?
- Why must a chat template be versioned and reviewed as a release artifact rather than treated as invisible formatting?
17. Limitations and scope boundaries
This chapter explains decoder-oriented text generation and the surrounding application controls. It does not teach model training, RAG construction, multimodal tokenization, autonomous agent loops, MCP, or serving operations; later Module 00 chapters own those subjects. Retrieved content and tools appear here only where they affect the request boundary.
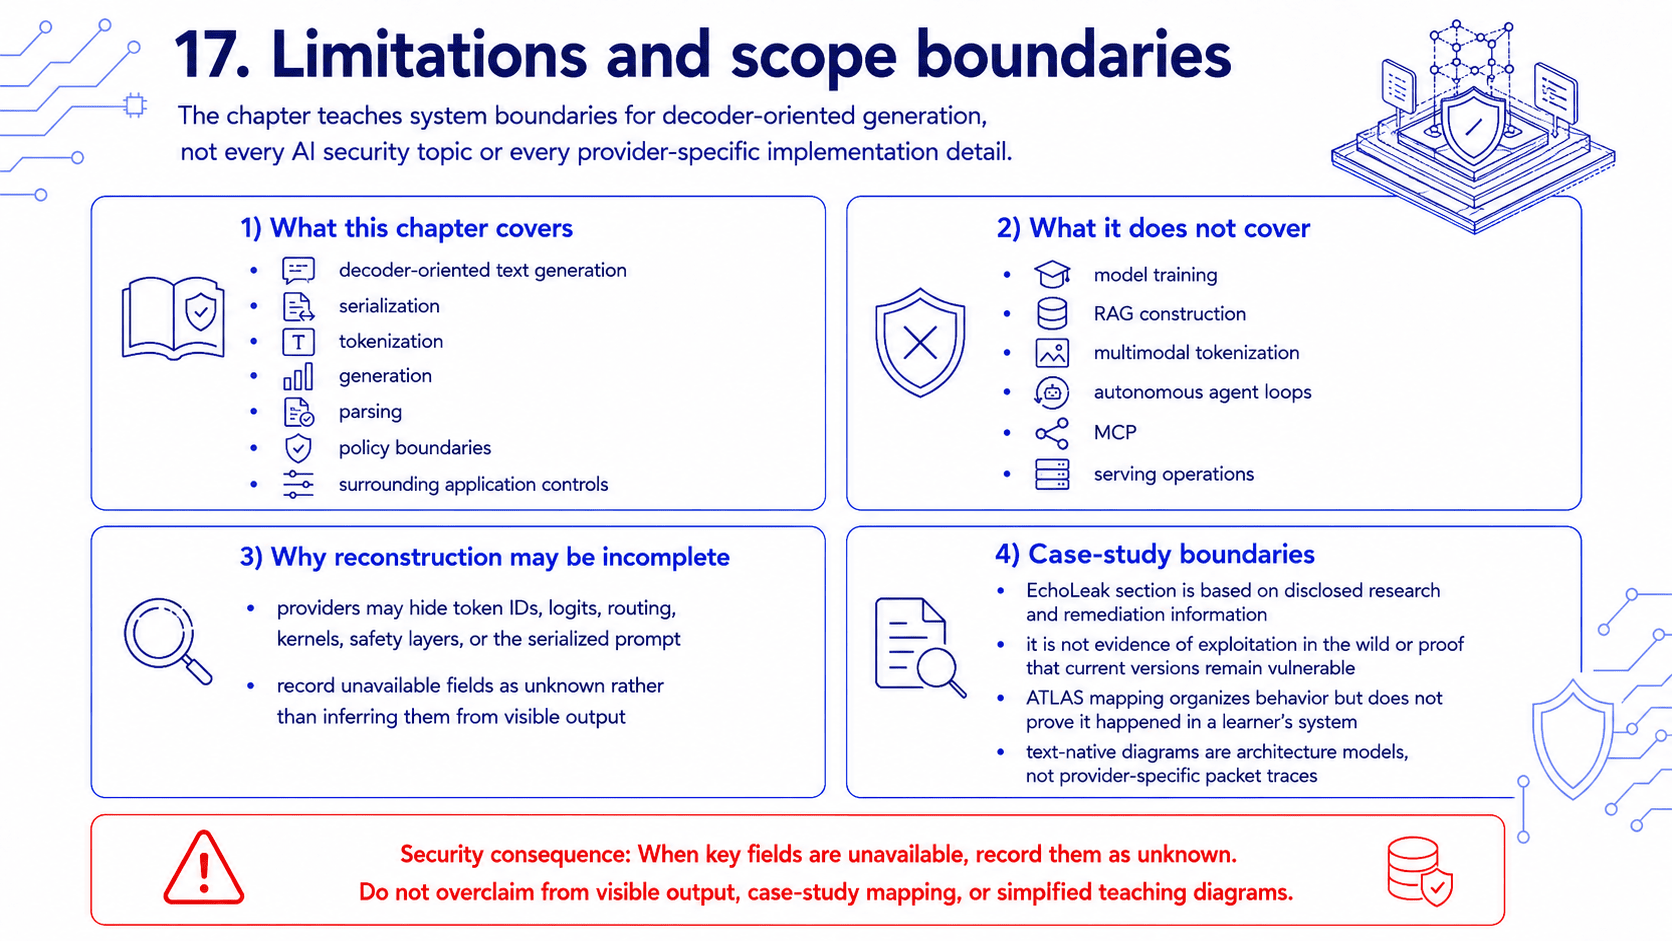
The conceptual equations and flows are architecture-neutral teaching models. A deployed provider may hide token IDs, logits, routing, kernels, safety layers, or the serialized prompt, so a complete forensic reconstruction may be impossible. Record unavailable fields as unknown rather than inferring them from visible output.
The EchoLeak section is based on a disclosed research case, Microsoft remediation information, and the MITRE ATLAS case record. It is not evidence of exploitation in the wild or a claim that current Microsoft 365 Copilot versions remain vulnerable. Likewise, an ATLAS mapping organizes validated behavior; it does not prove that the behavior occurred in a learner's system.
The chapter preserves the published infographics alongside text-native diagrams, tables, descriptive alternative text, and captions. The text-native versions keep logical stages selectable and searchable; the raster visuals provide the original publication context. Treat both as architecture models, not packet-level or provider-specific implementation diagrams.
18. Key takeaways
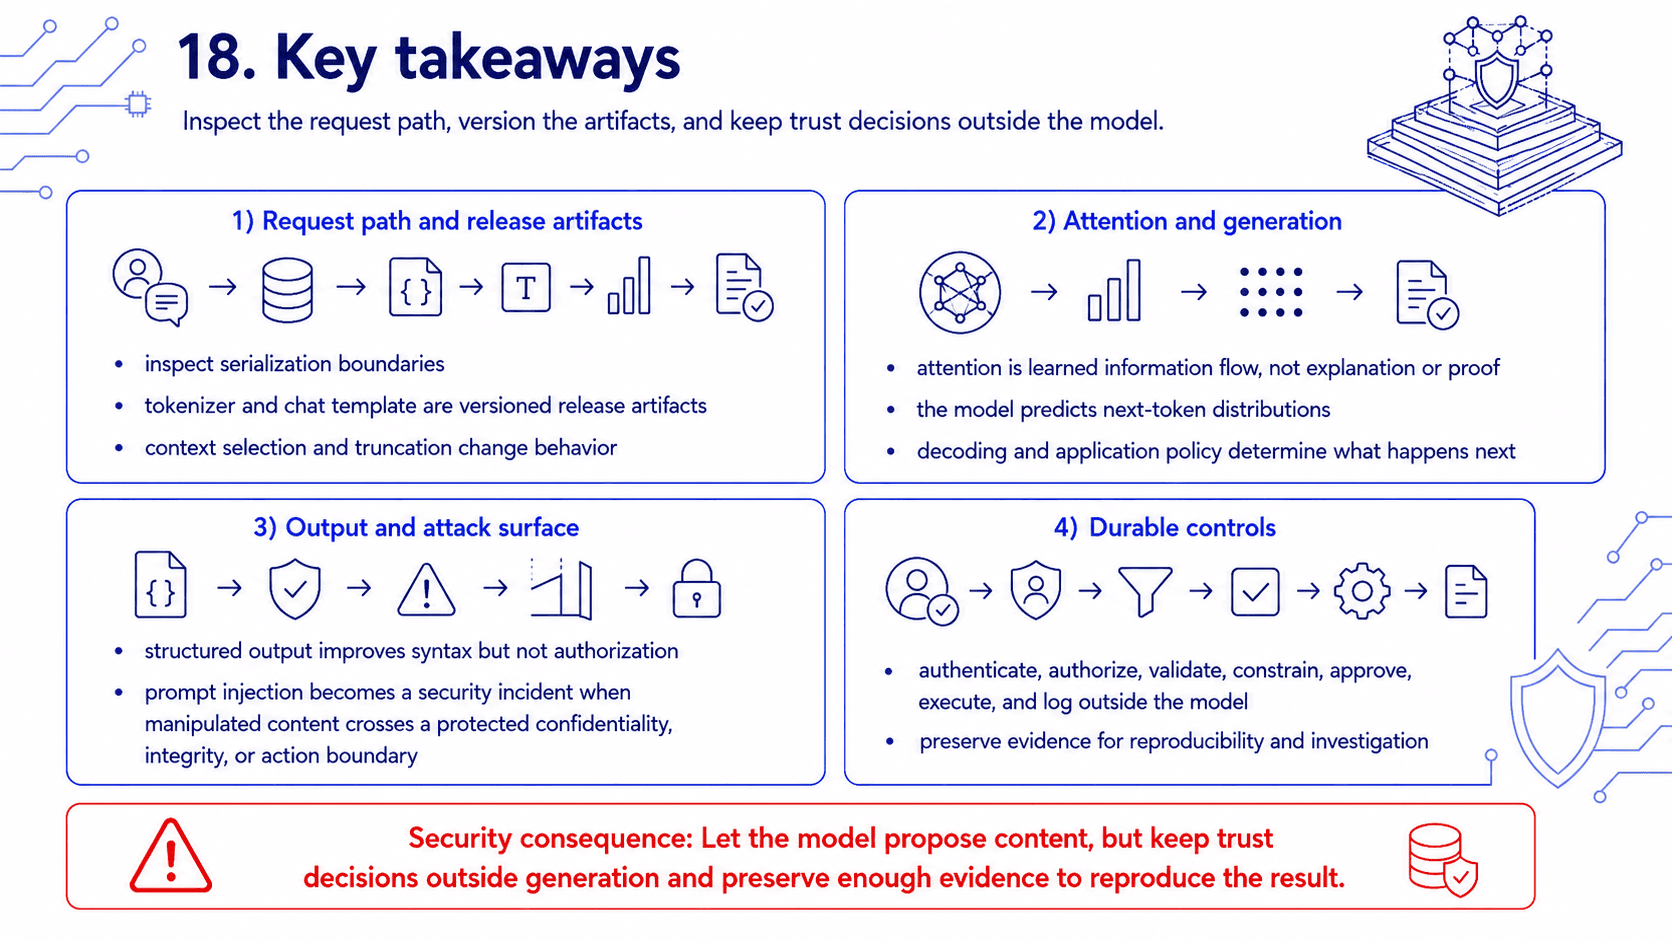
- A chat application serializes structured state into a token sequence; inspect the serialization boundary.
- Tokenizer and chat template are versioned release artifacts, not invisible preprocessing details.
- Attention is learned information flow, not explanation, permission, provenance, or truth.
- An LLM repeatedly predicts a next-token distribution; decoding and application policy determine what happens next.
- Context limits, truncation, caches, routing, and generation configuration can change behavior and evidence.
- Structured output improves syntax but does not establish authorization or semantic safety.
- Prompt injection becomes a security incident when manipulated content crosses a protected confidentiality, integrity, or action boundary.
- Durable controls authenticate, authorize, validate, constrain, approve, execute, and log outside the model.
19. What comes next
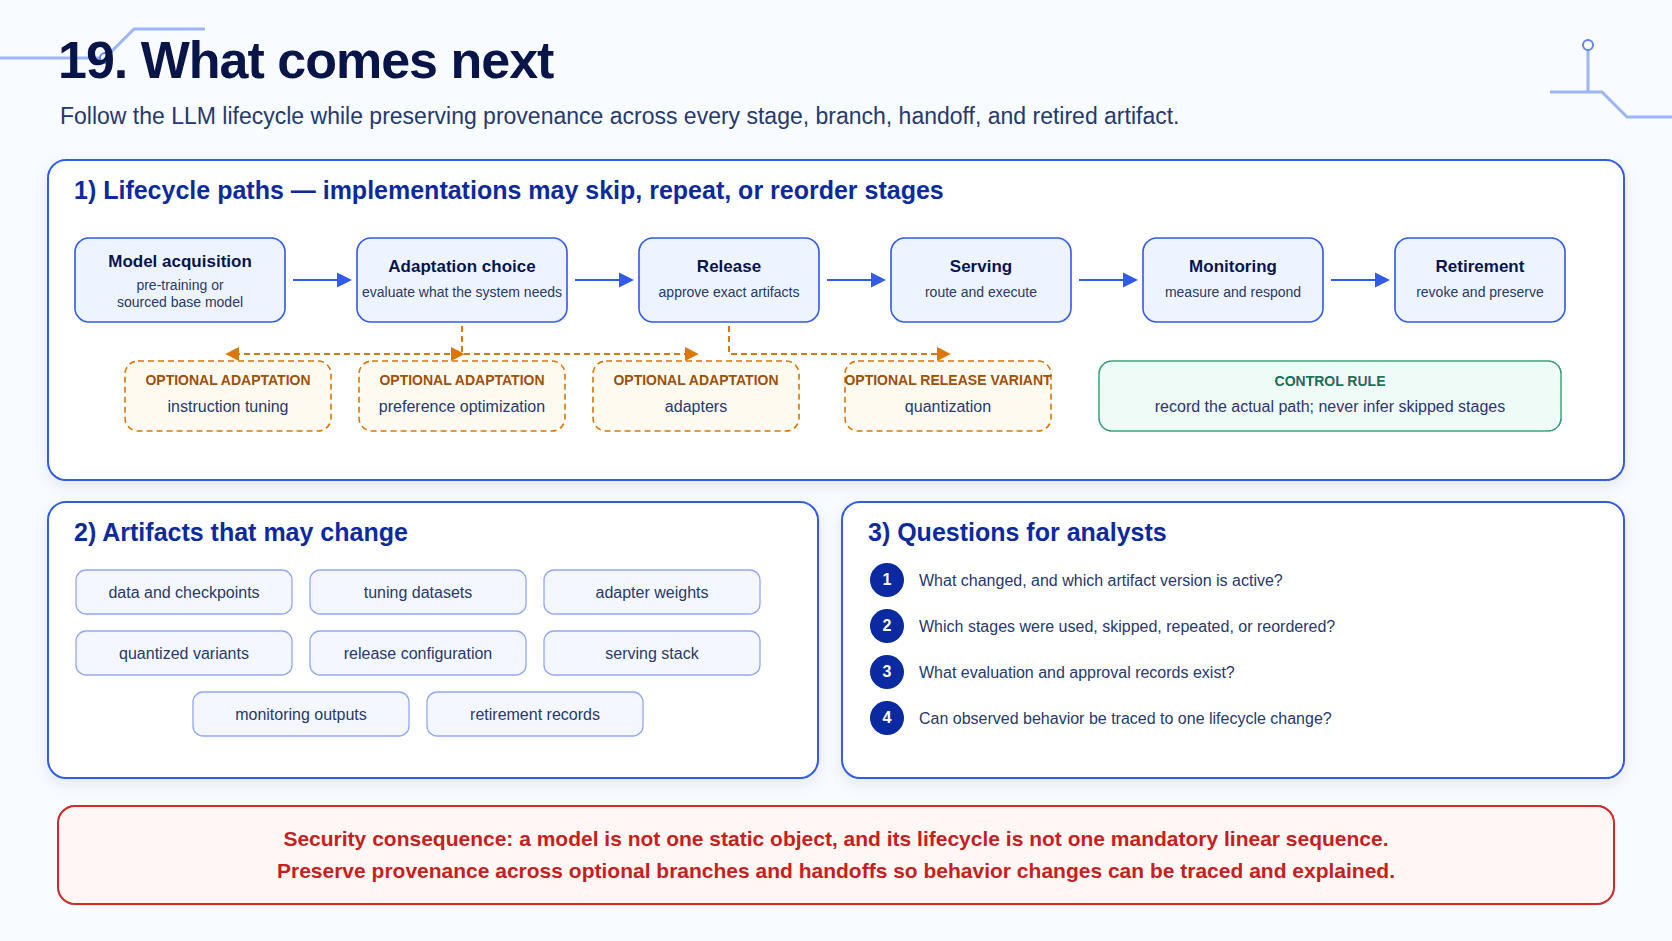
The next Module 00 chapter follows the LLM lifecycle from pre-training through instruction tuning, preference optimization, adapters, quantization, release, serving, monitoring, and retirement. It will show which artifacts change at each stage and how to preserve provenance across them.
20. Conclusion
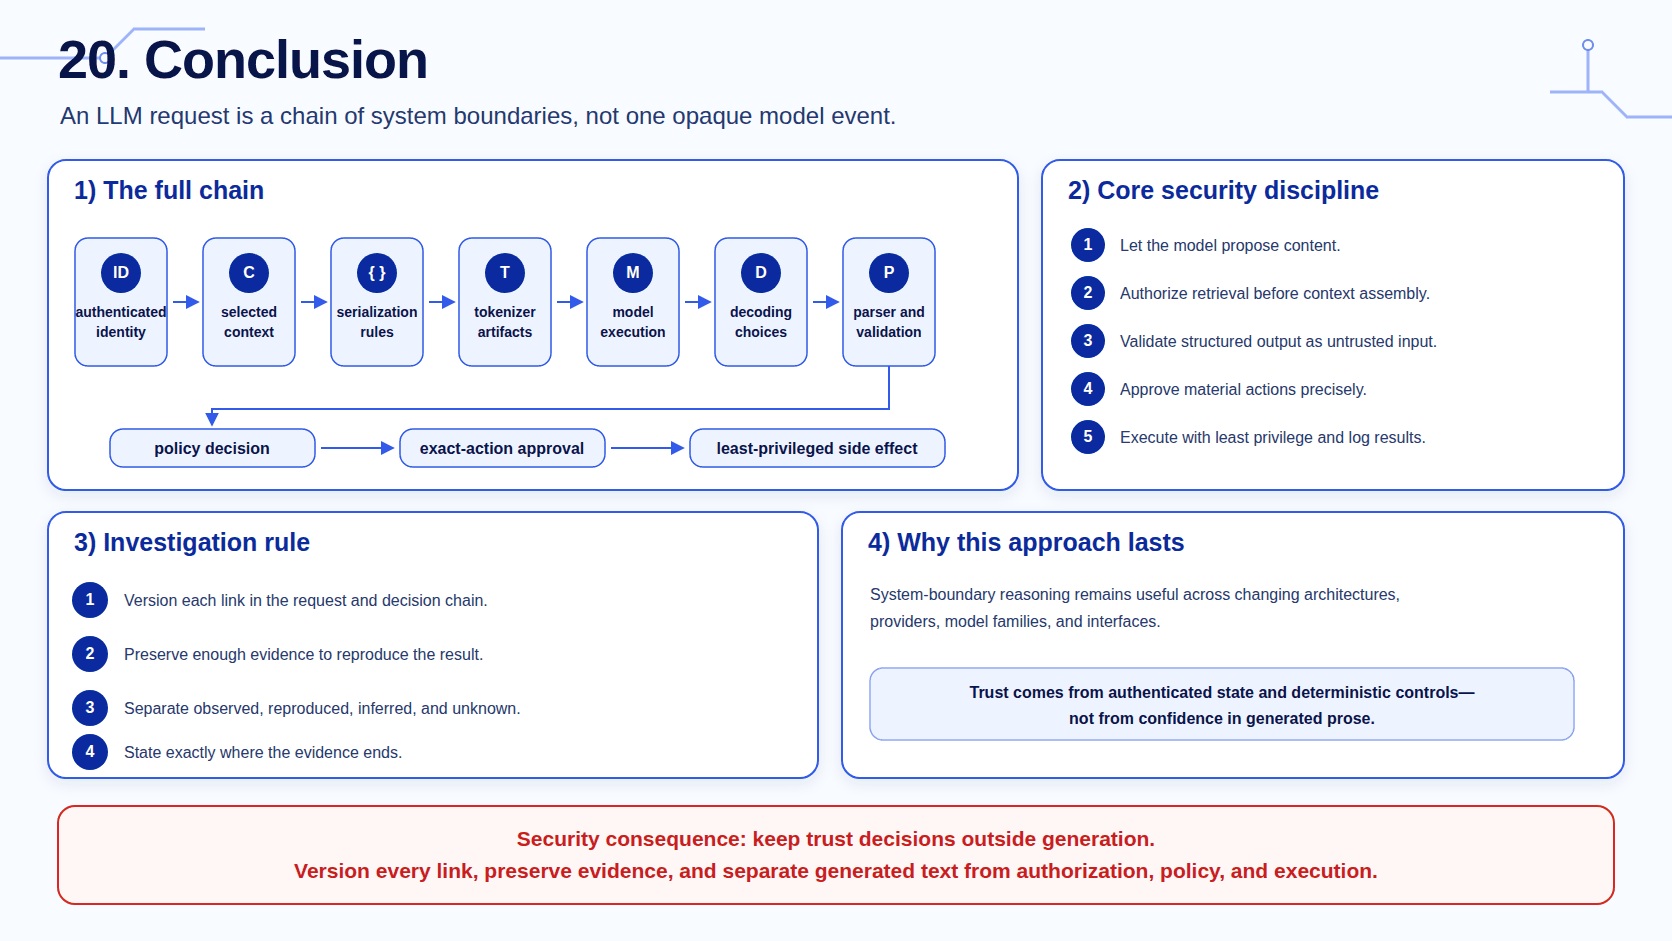
An LLM request is not one opaque model event. It is a chain of authenticated identities, selected context, serialization rules, tokenizer artifacts, model execution, decoding choices, parsers, policy decisions, and possible side effects. Investigations become defensible when each link is versioned and the analyst states exactly where the evidence ends.
The central security discipline is therefore simple: let the model propose content, but keep trust decisions outside generation. Authorize retrieval before context assembly, validate structured output as untrusted input, approve material actions precisely, execute with least privilege, and preserve enough evidence to reproduce the result. This approach remains useful even as architectures and providers change because it is grounded in system boundaries rather than confidence in generated prose.
Chapter 4 status: complete. Originally published 15 August 2026 and finalized 31 August 2026. The wider AI Security Engineering course remains under construction.
21. References
- Vaswani, A. et al., Attention Is All You Need, 2017 (revised 2023).
- Hugging Face Transformers v5.15.1, Chat templates, Tokenizer summary, and KV cache strategies.
- Hugging Face Transformers v5.15.1, Generation strategies.
- NIST, Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations, NIST AI 100-2 E2025, 2025.
- NIST, Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile, NIST AI 600-1, 2024.
- MITRE, ATLAS and ATLAS content release 2026.07 (Git tag
v2026.07), accessed 31 August 2026. - Greshake, K. et al., Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection, 2023.
- Microsoft Security Response Center, CVE-2025-32711, 2025.
- MITRE ATLAS, EchoLeak: Zero-Click Prompt Injection Targeting M365 Copilot for Data Exfiltration (
AML.CS0059), ATLAS content release 2026.07. - OWASP, GenAI LLM Top 10 2026, 3 August 2026; use as community guidance rather than a substitute for a system-specific threat model.
- Pavan Reddy and Aditya Sanjay Gujral, EchoLeak: The First Real-World Zero-Click Prompt Injection Exploit in a Production LLM System, AAAI Symposium Series, 2025.
- Su, J. et al., RoFormer: Enhanced Transformer with Rotary Position Embedding, 2021.
- Jain, S. and Wallace, B. C., Attention is not Explanation, NAACL-HLT, 2019.
22. Follow My Work
I publish practical cybersecurity research, CTI workflows, detection engineering notes, malware-analysis projects, AI-security research, open-source tools, labs, and technical guides.